Xinggang Wang
Professor
Artificial Intelligence Institute

Research interests: computer vision and deep learning, especially, visual representation learning, LLM architectures, physical AI, and agentic models.
Selected Projects
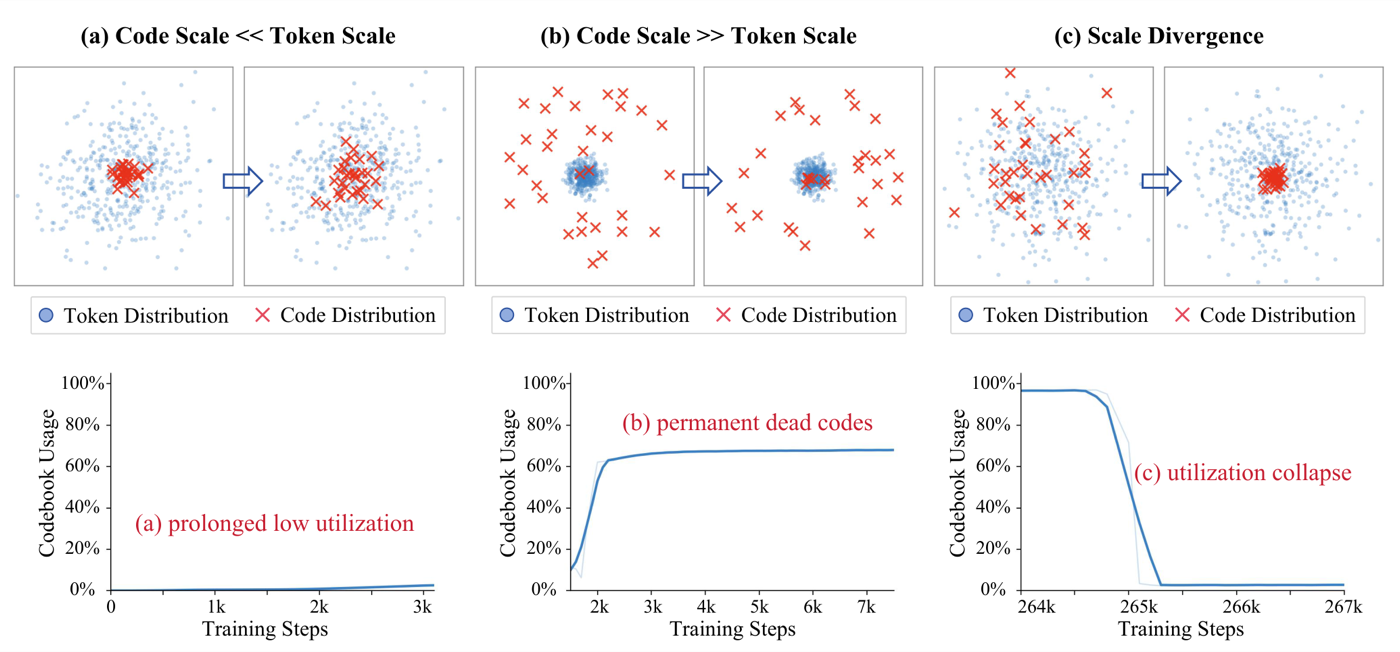 StableVQ
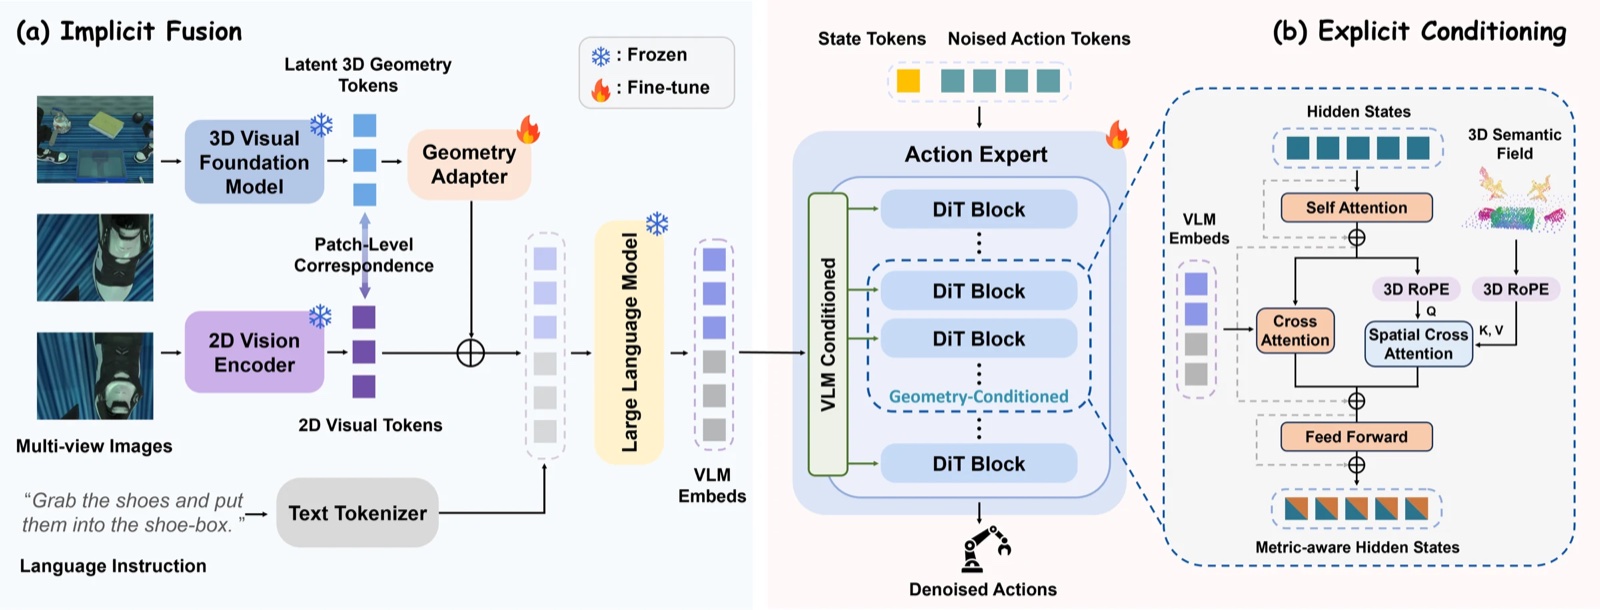 Bridge3D
 AdaRoboVLG
DreamWAM
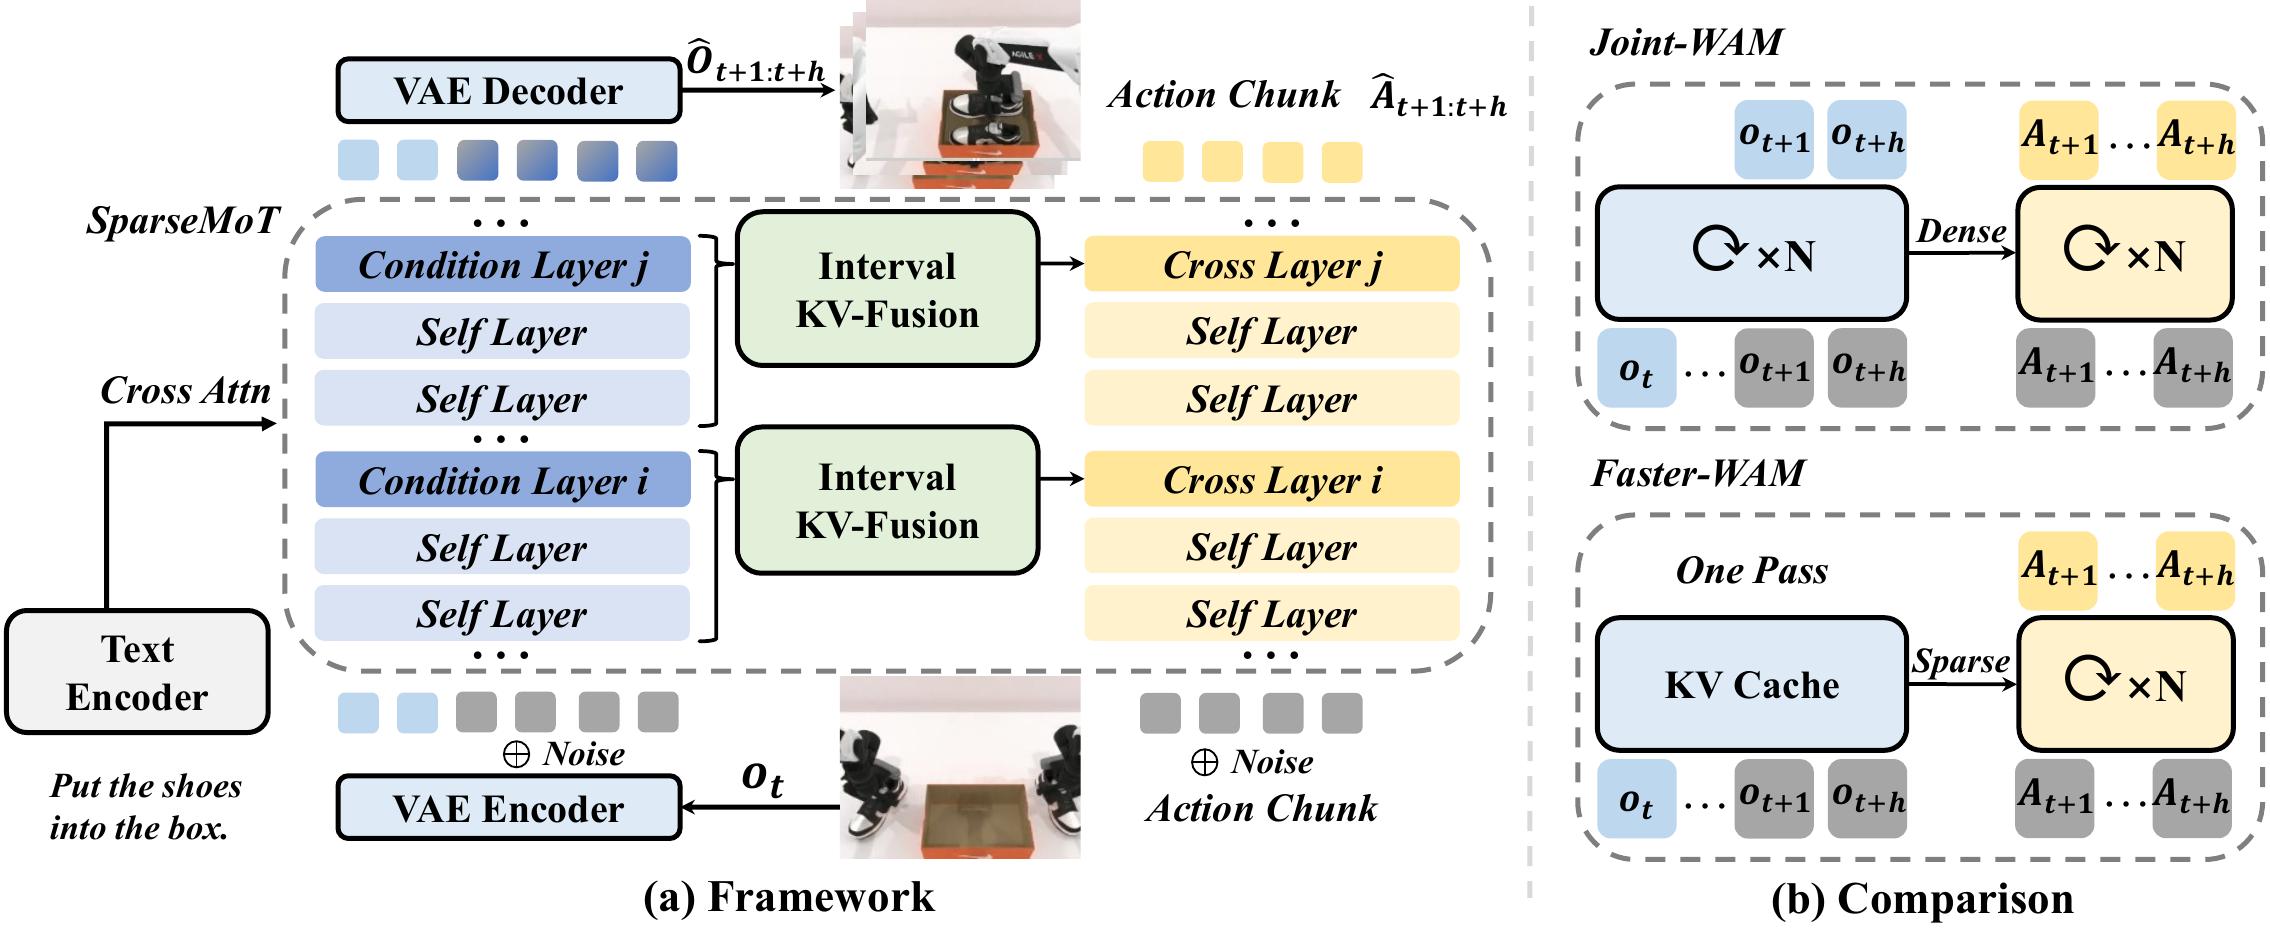 Faster-WAM
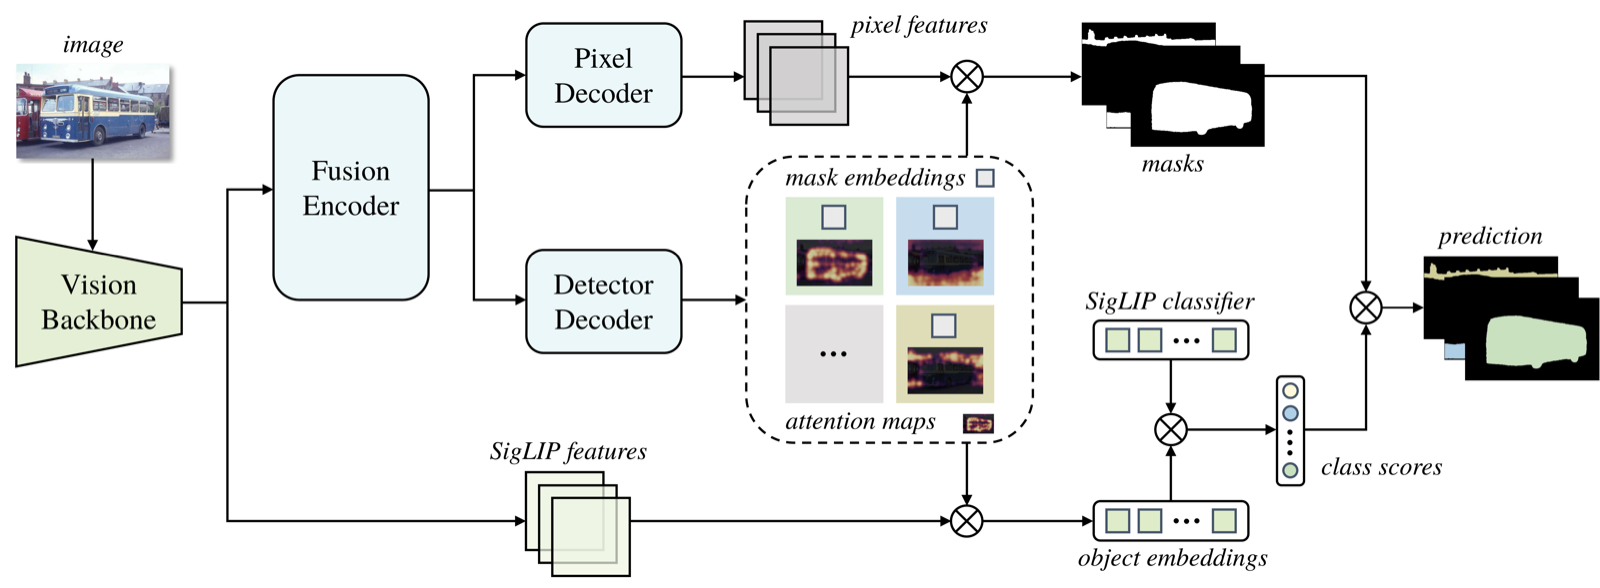 EOVSAM
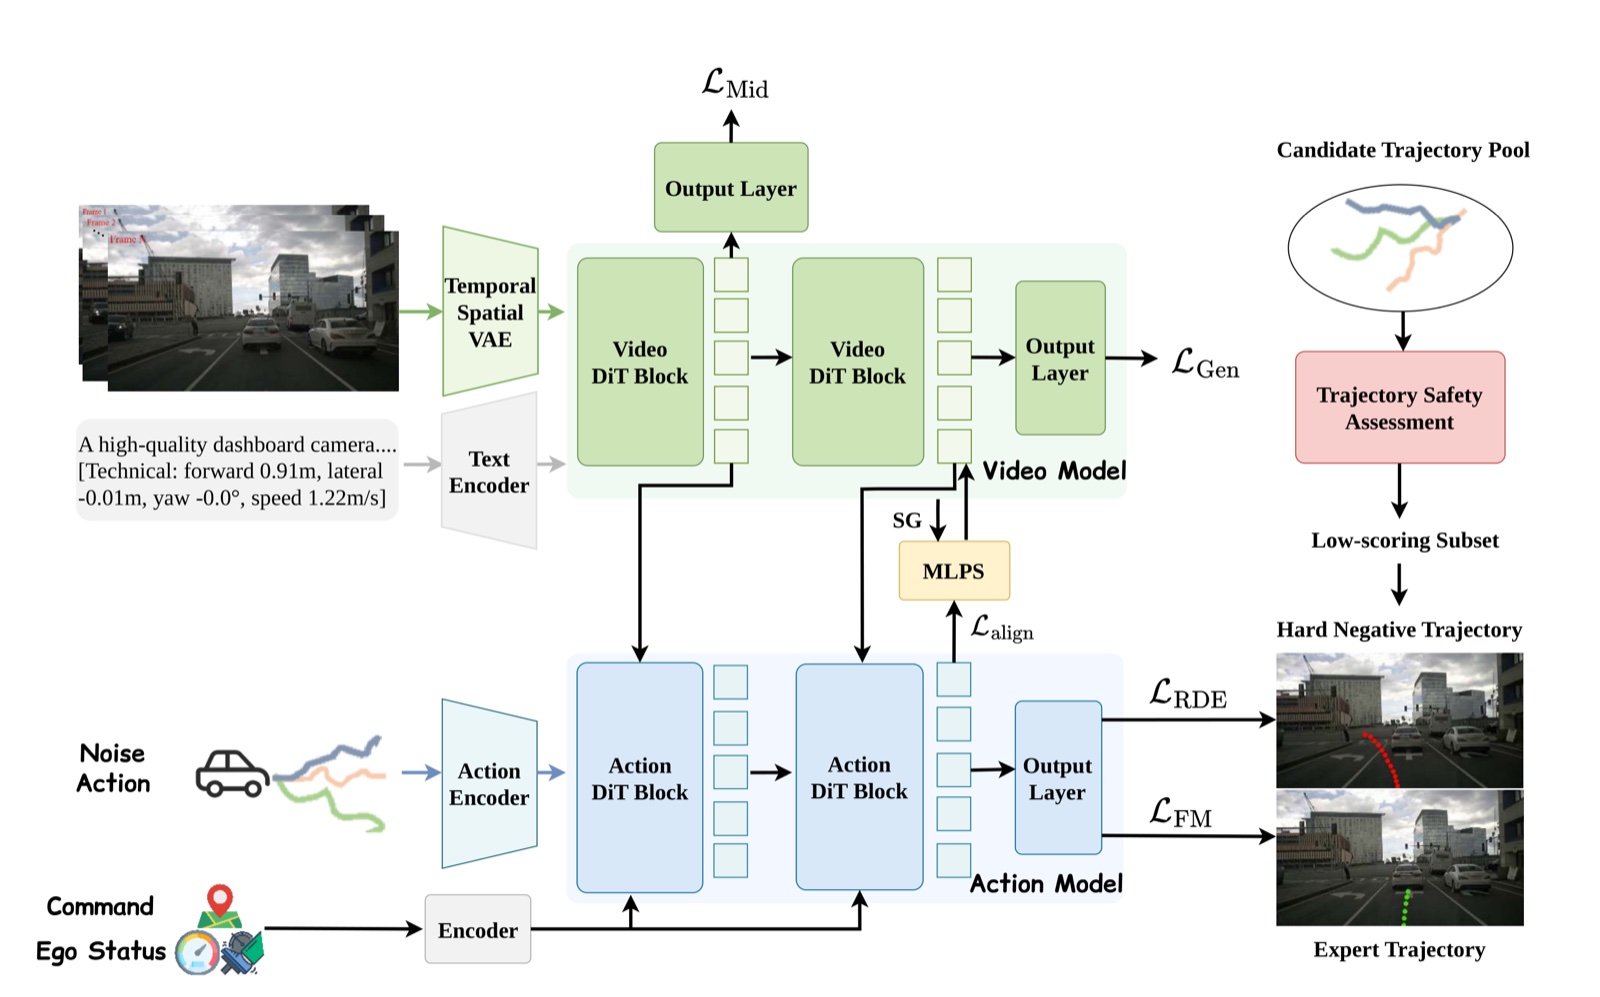 ReWorld
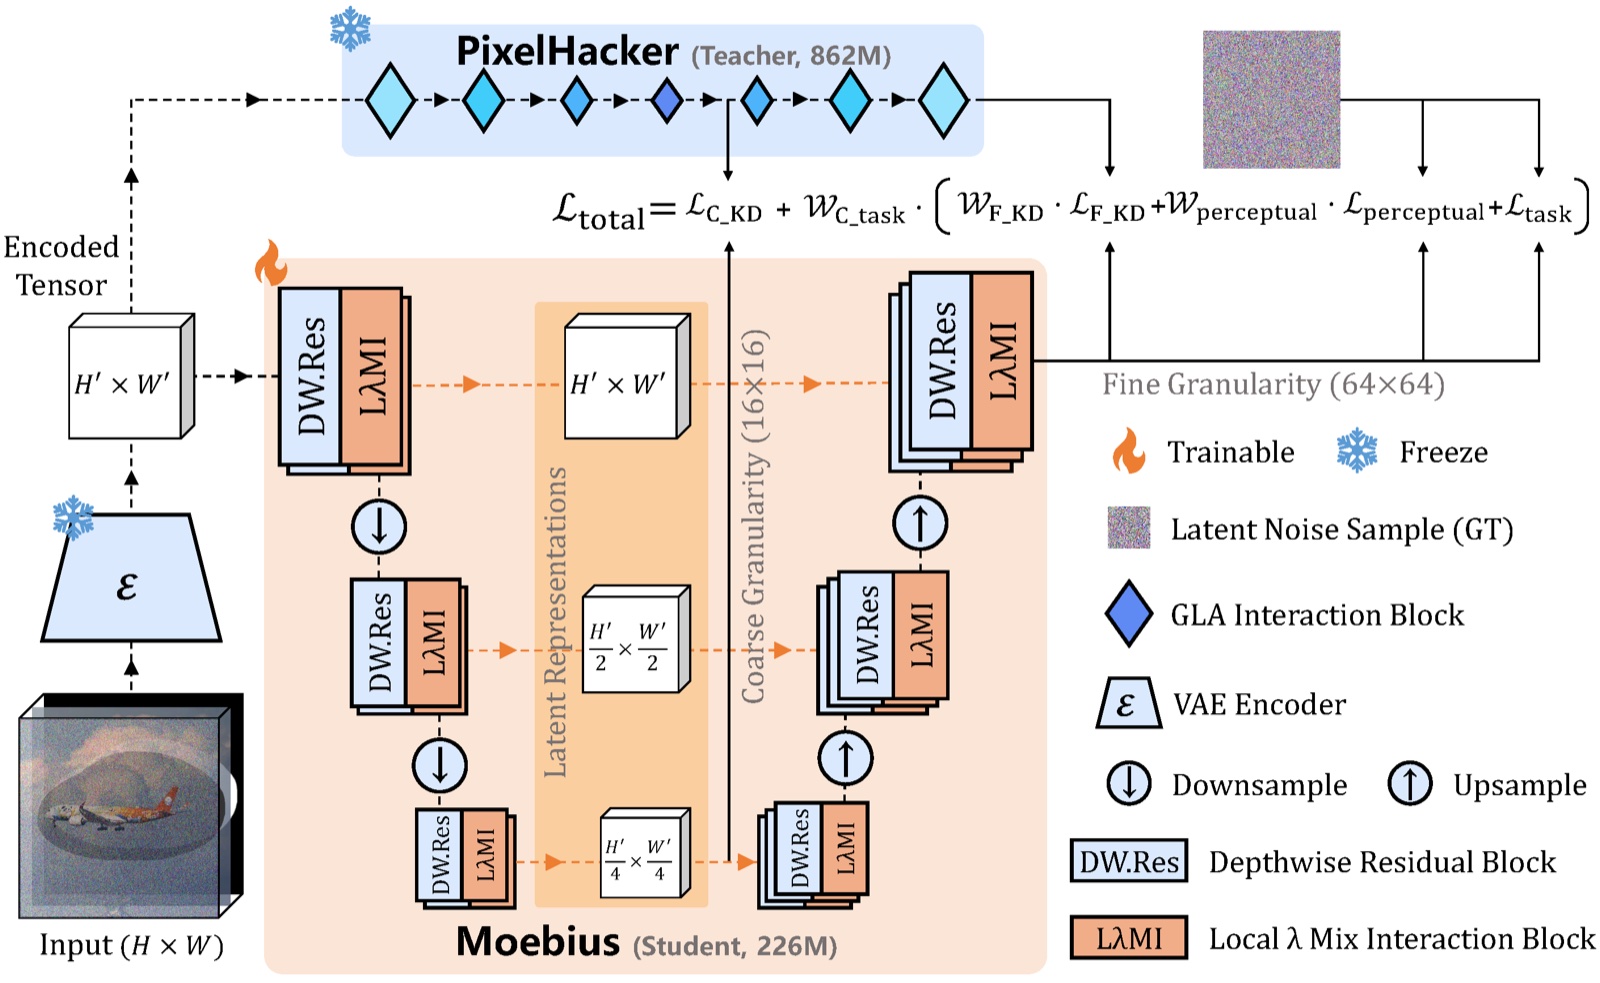 Moebius
MotionVLA
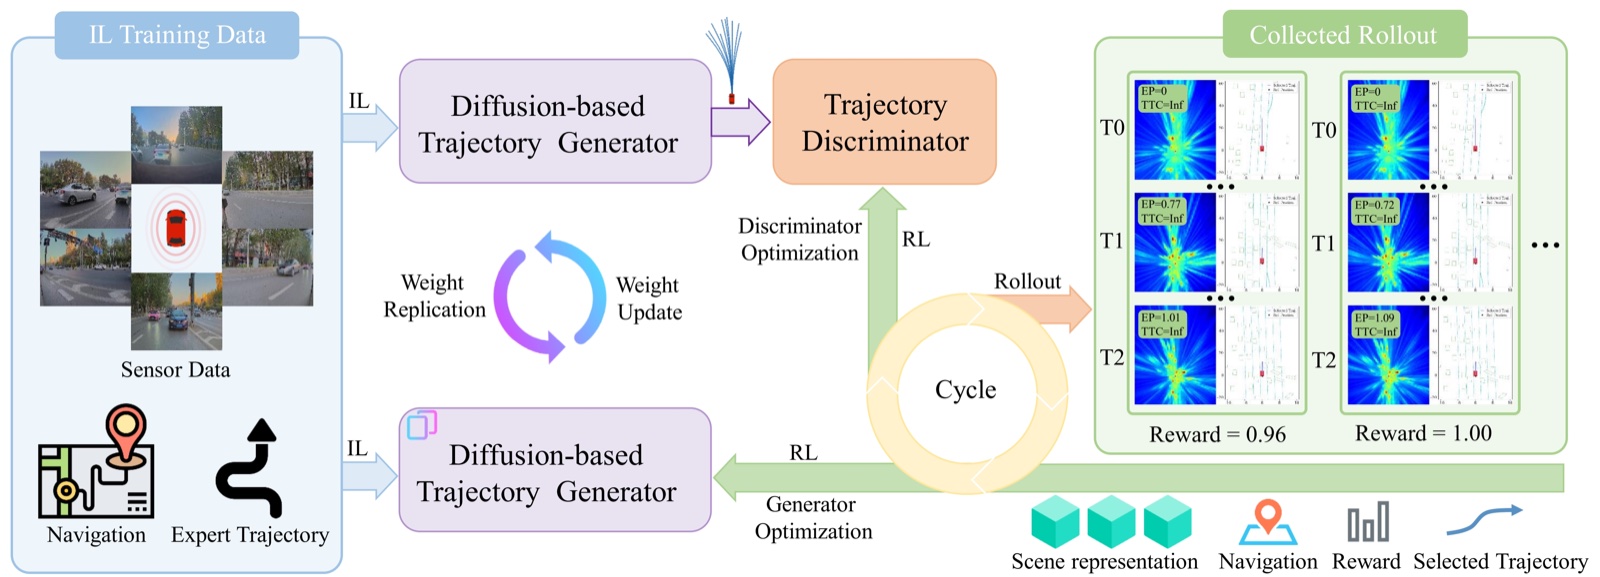 RAD-2
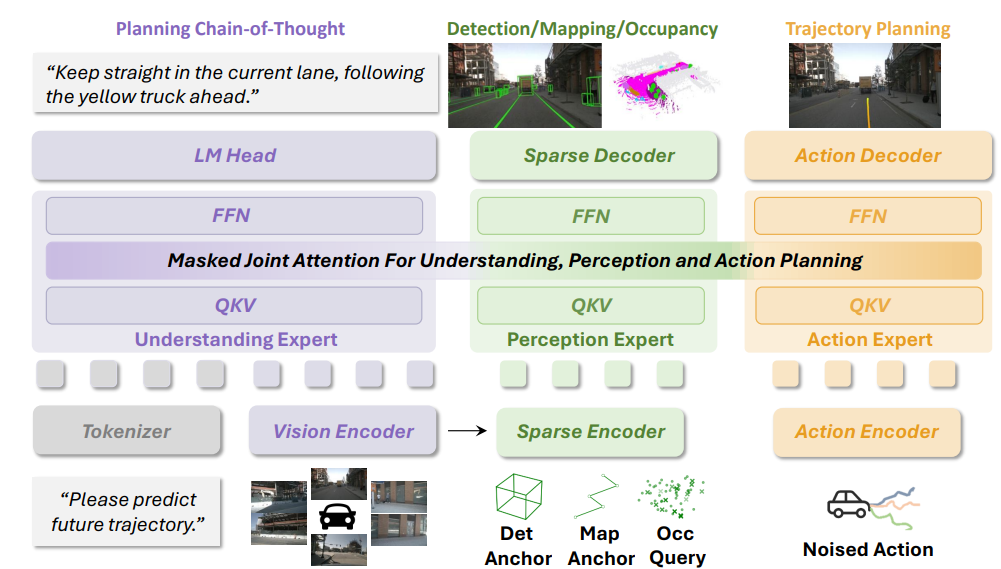 UniDriveVLA
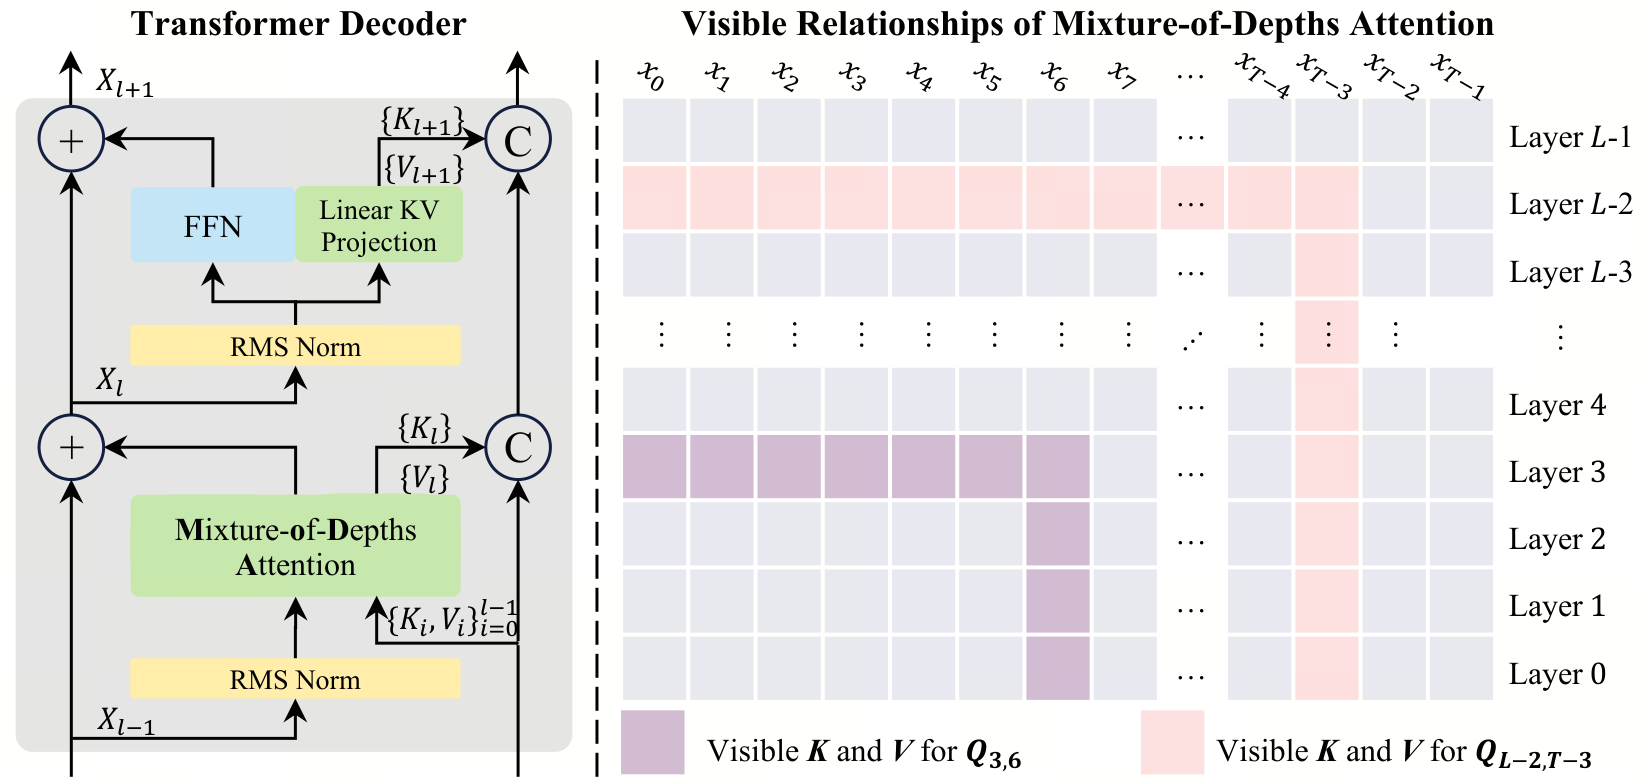 MoDA
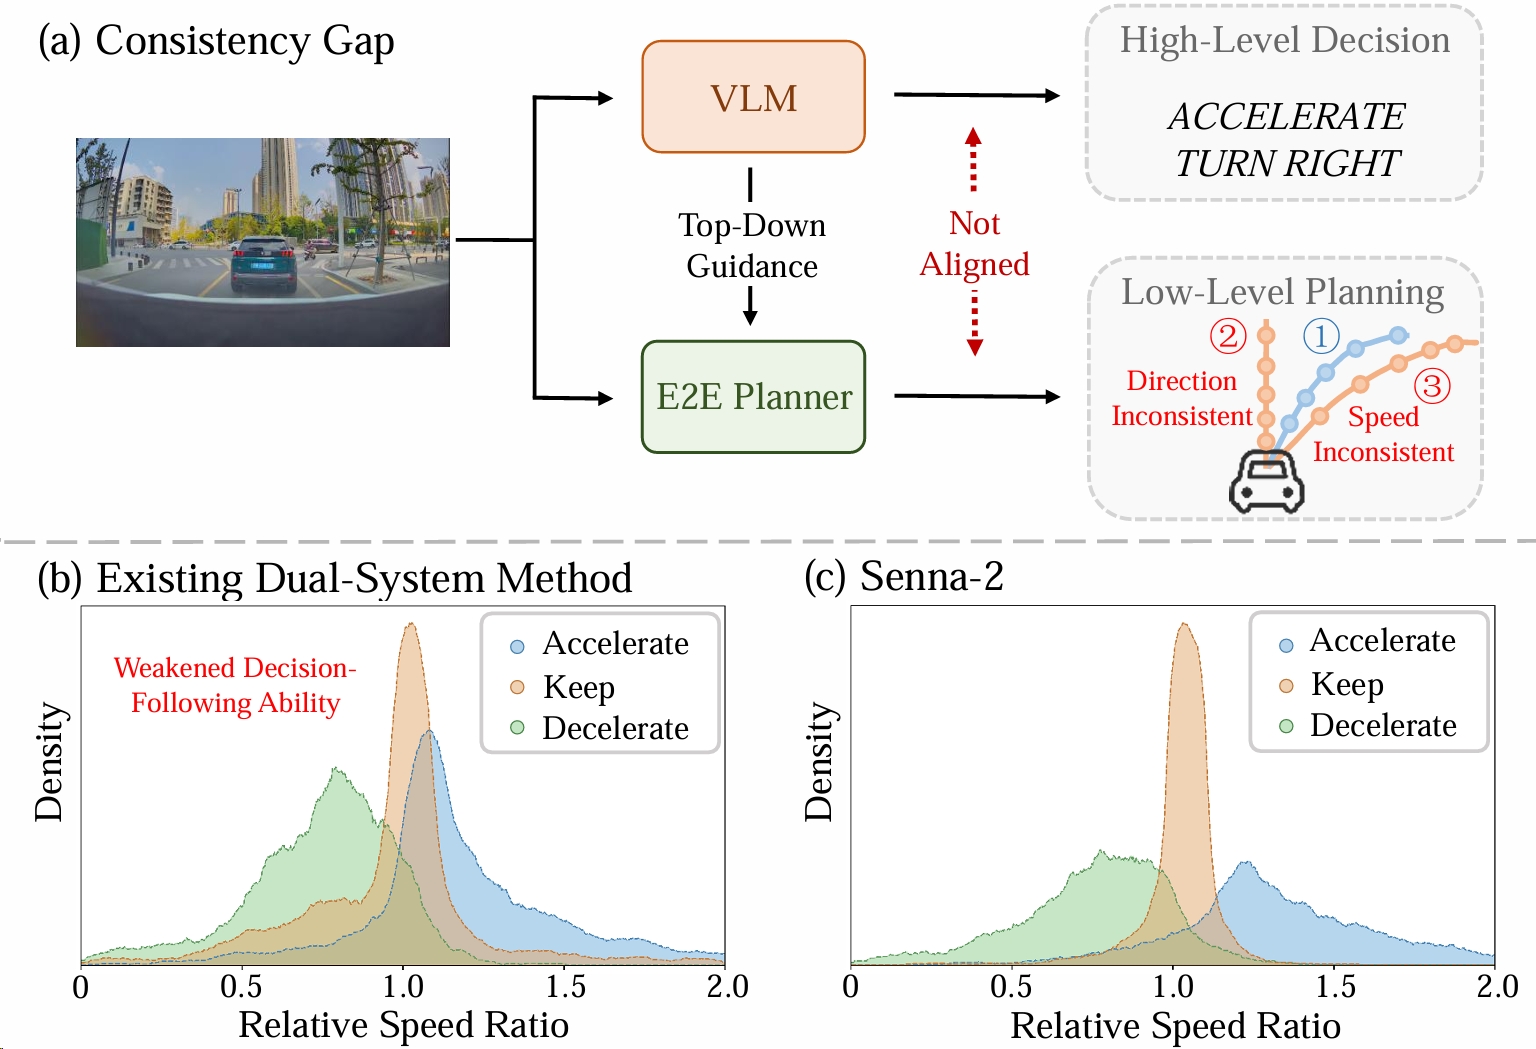 Senna-2
OmniTrack
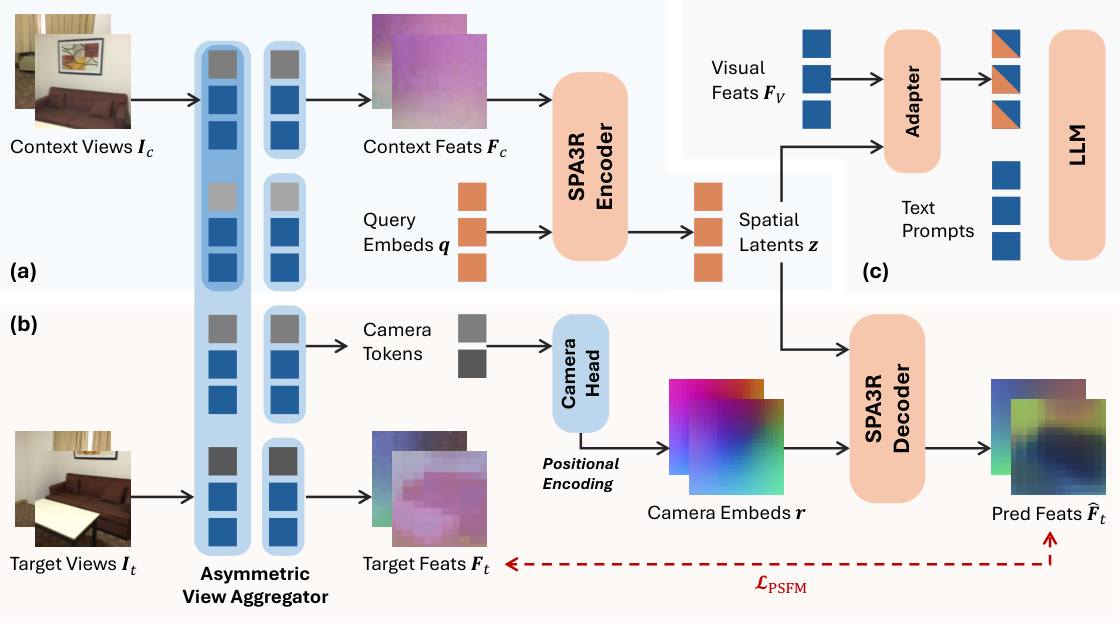 Spa3R
 DriveLaW
 DiffusionVL
 VTP
 InfiniteVL
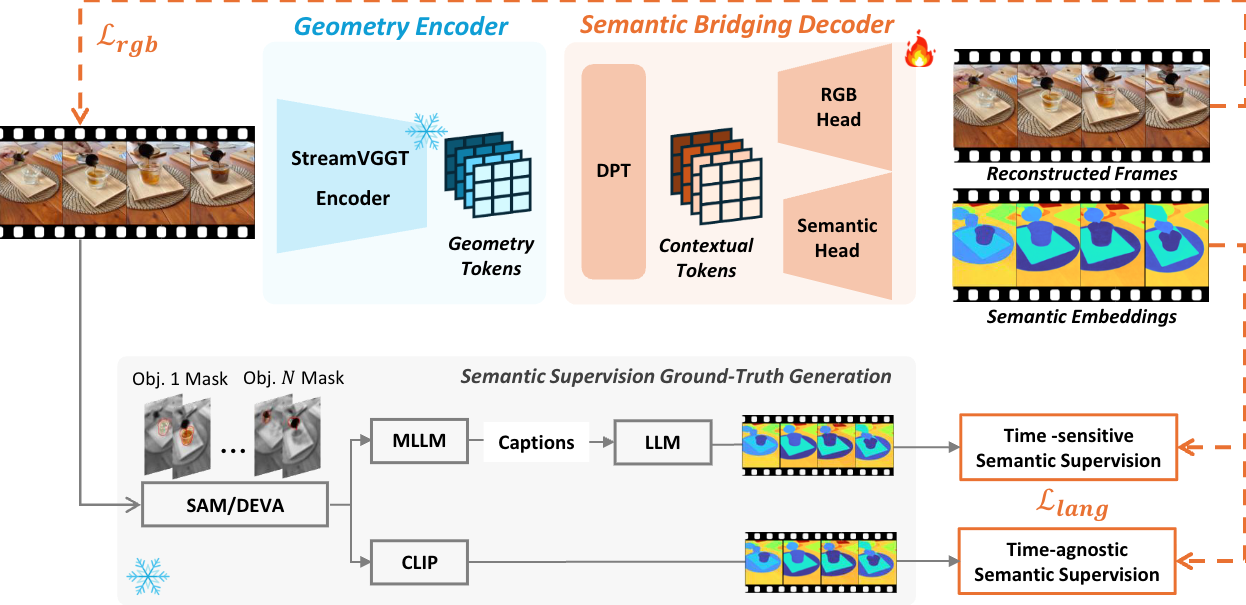 4DLangVGGT
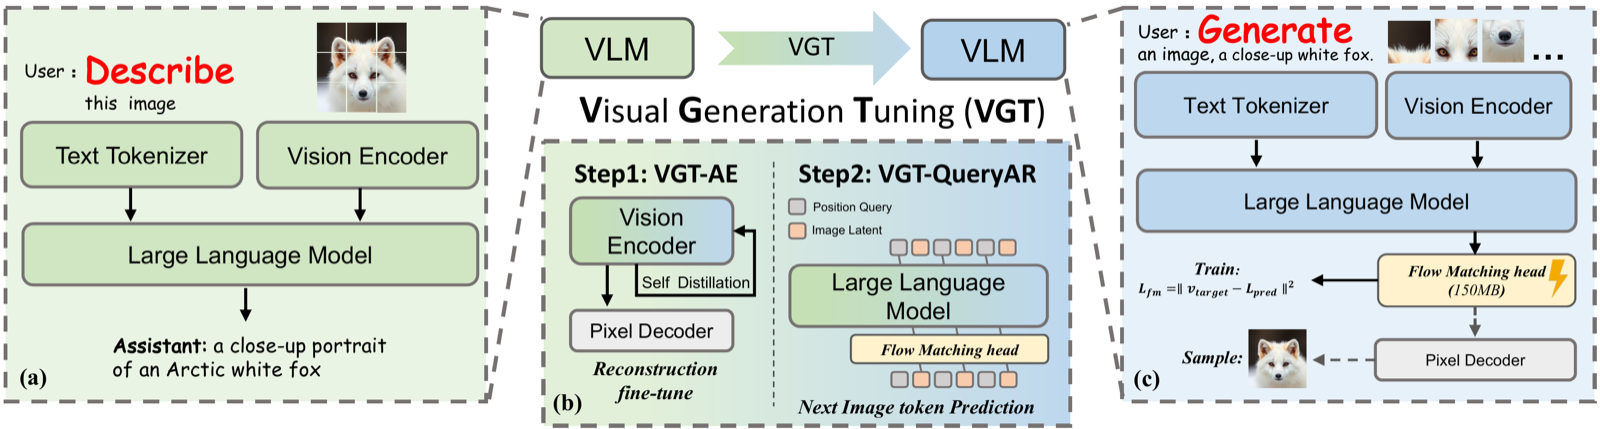 VGT
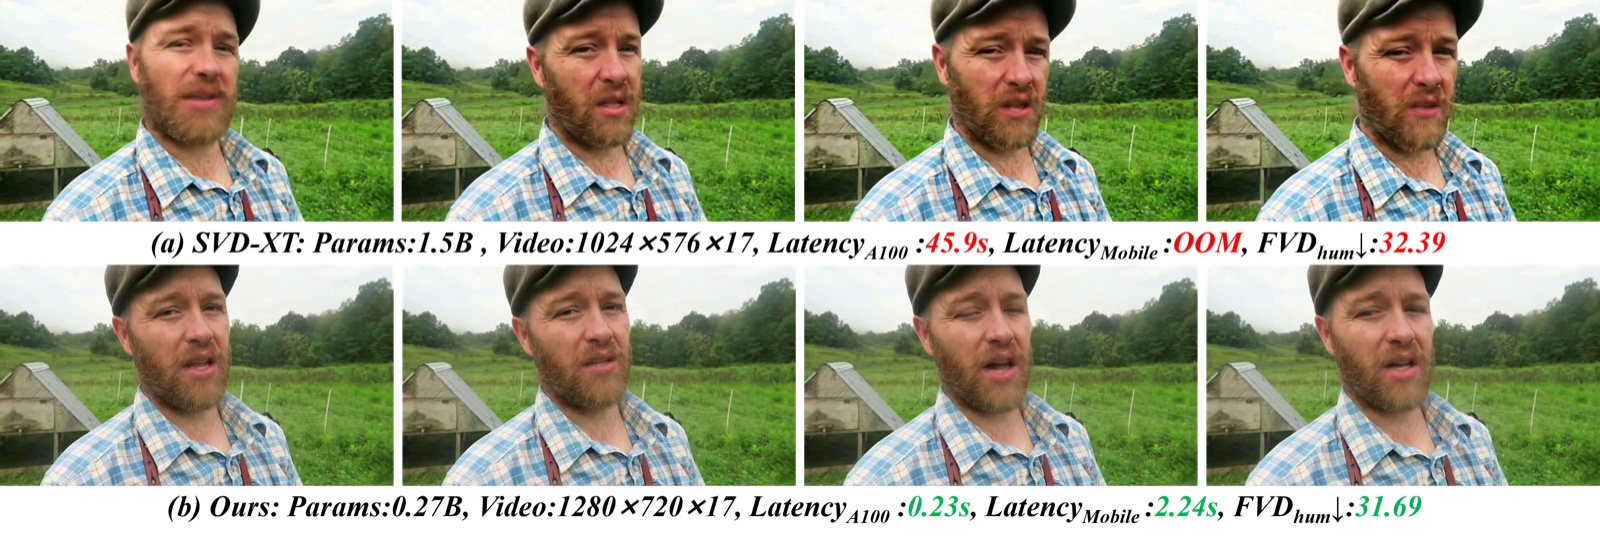 MobileI2V
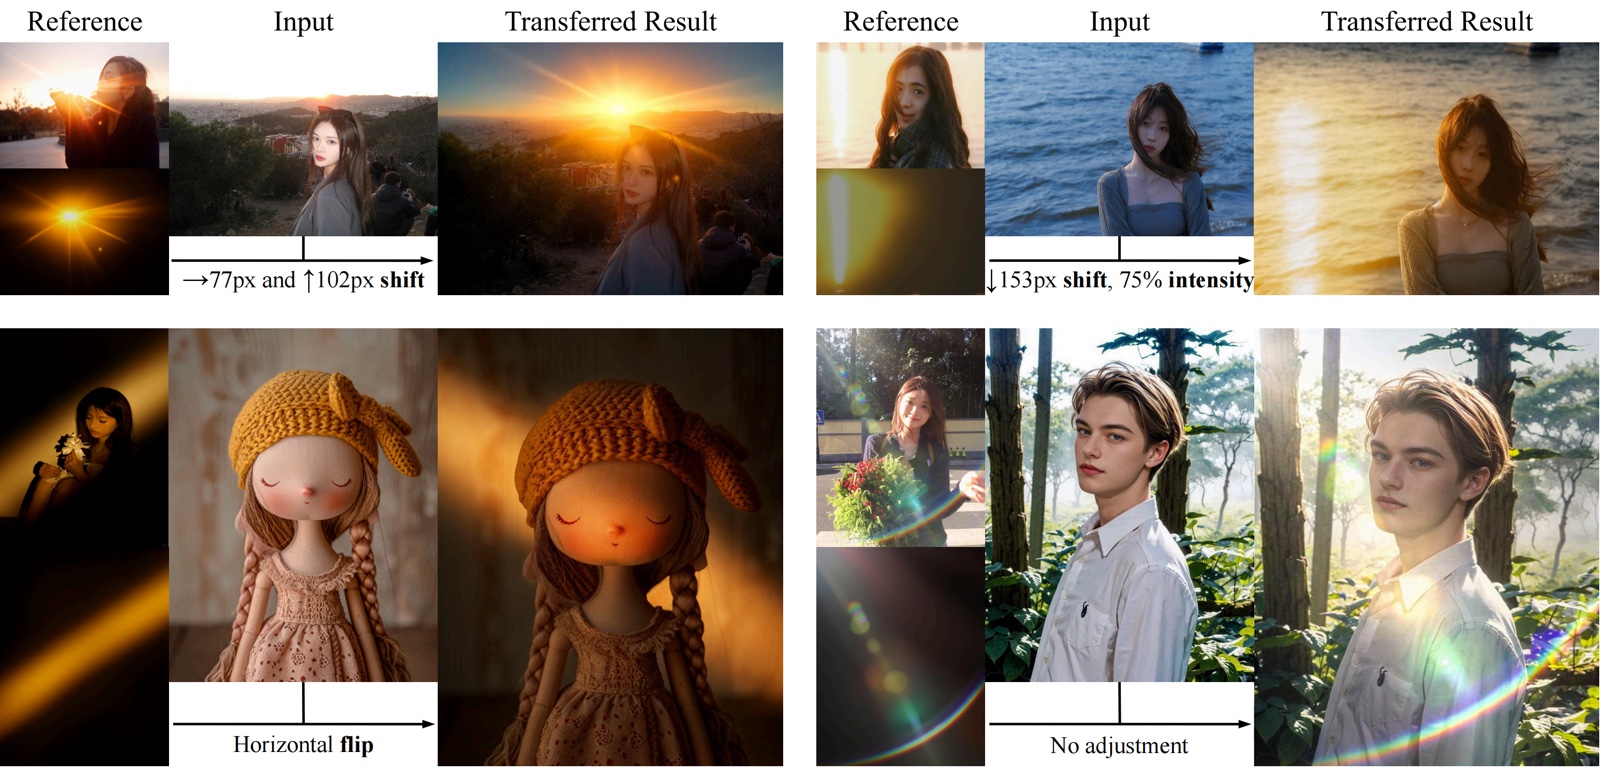 TransLight
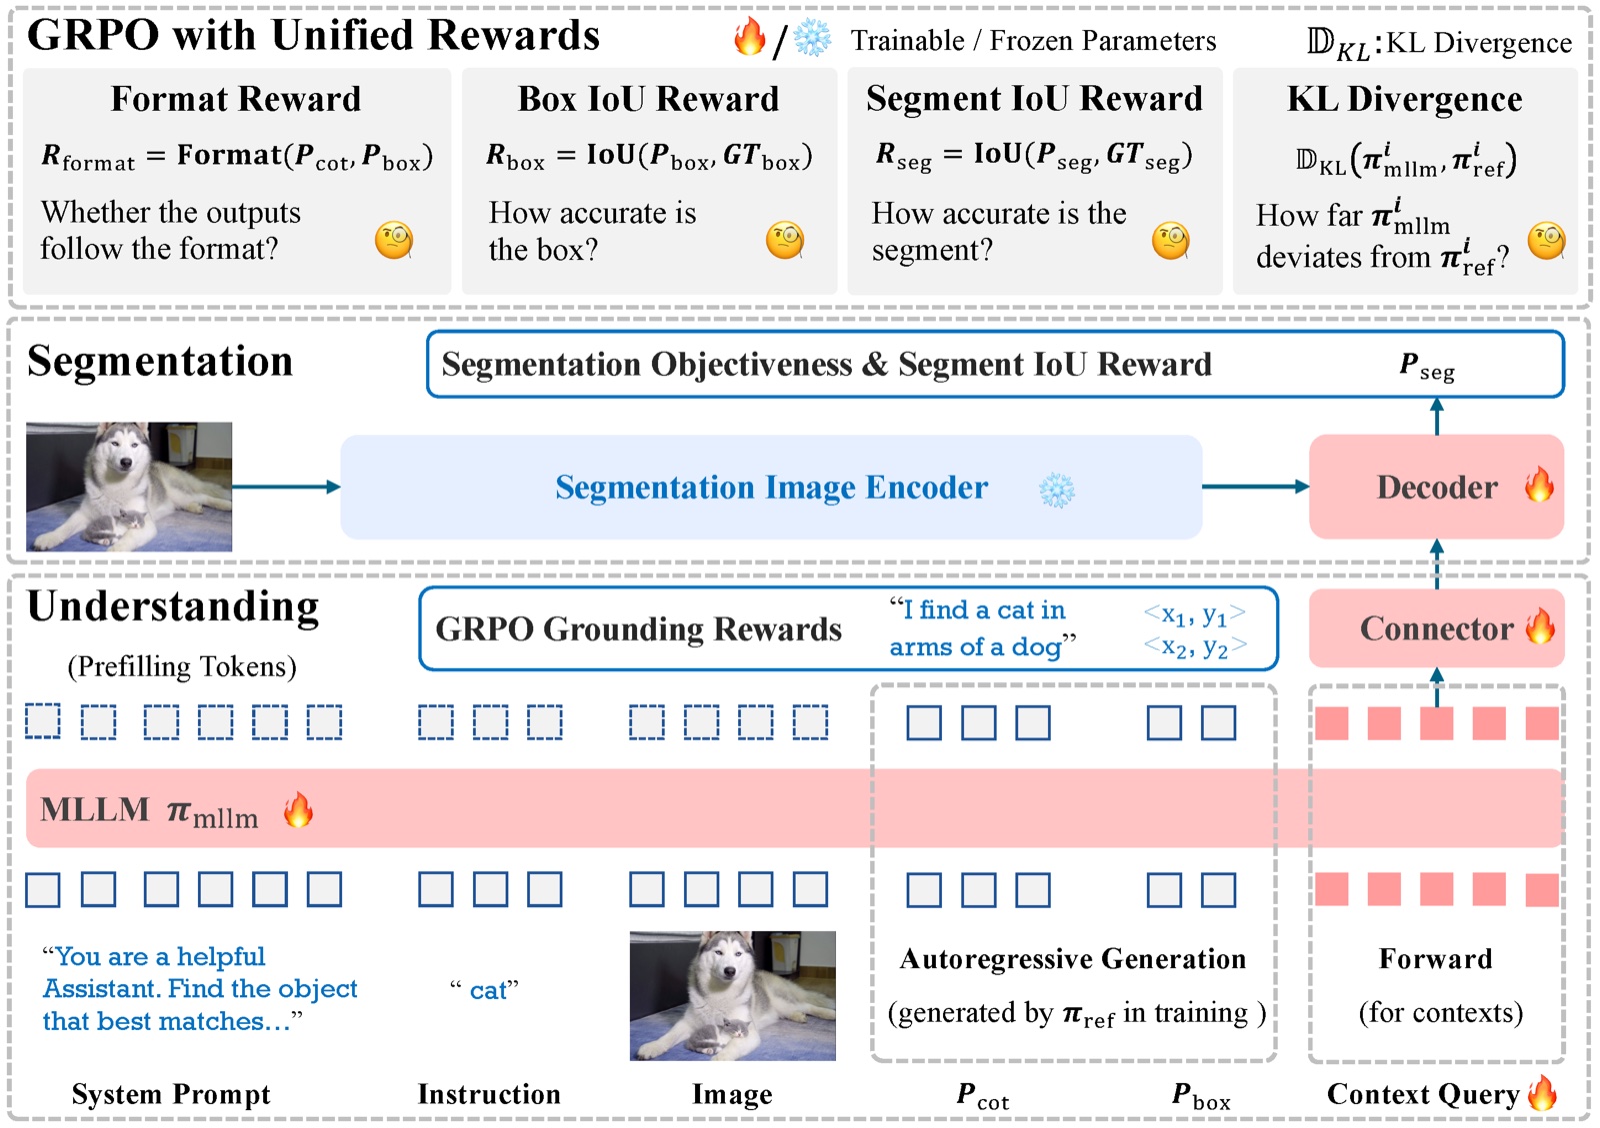 LENS
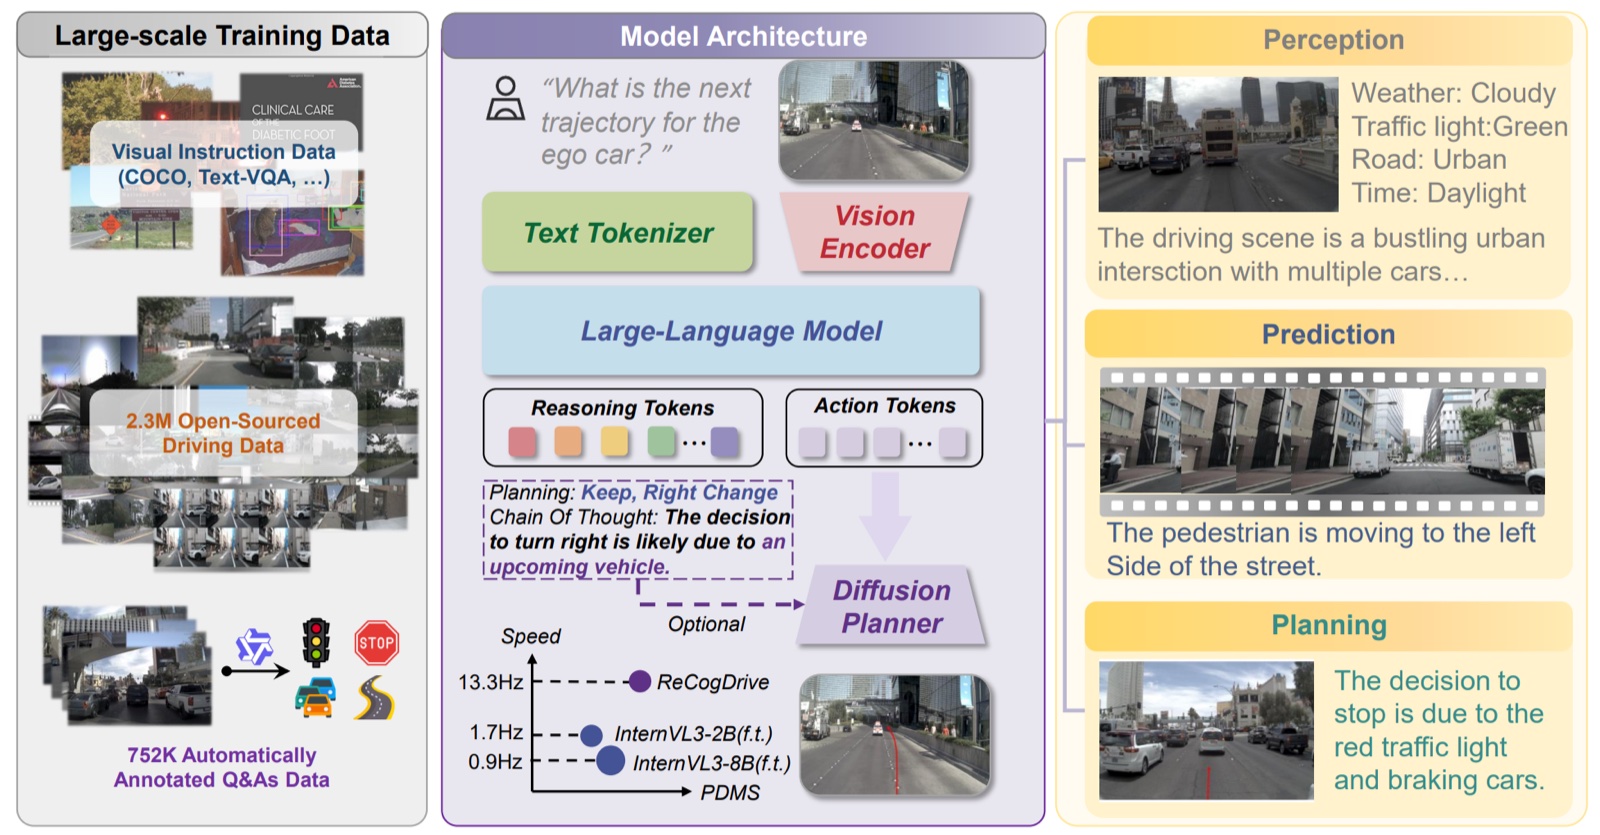 ReCogDrive
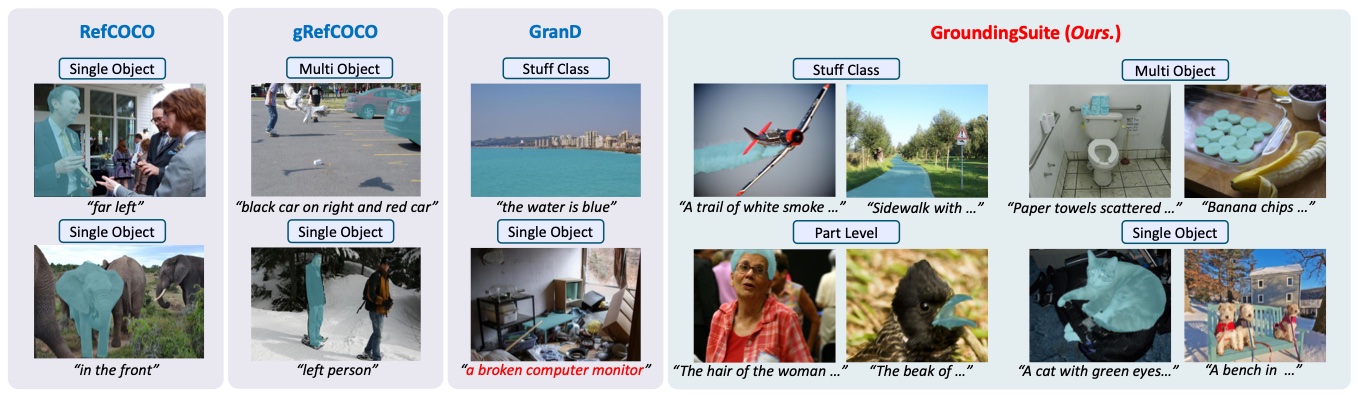 GroundingSuite
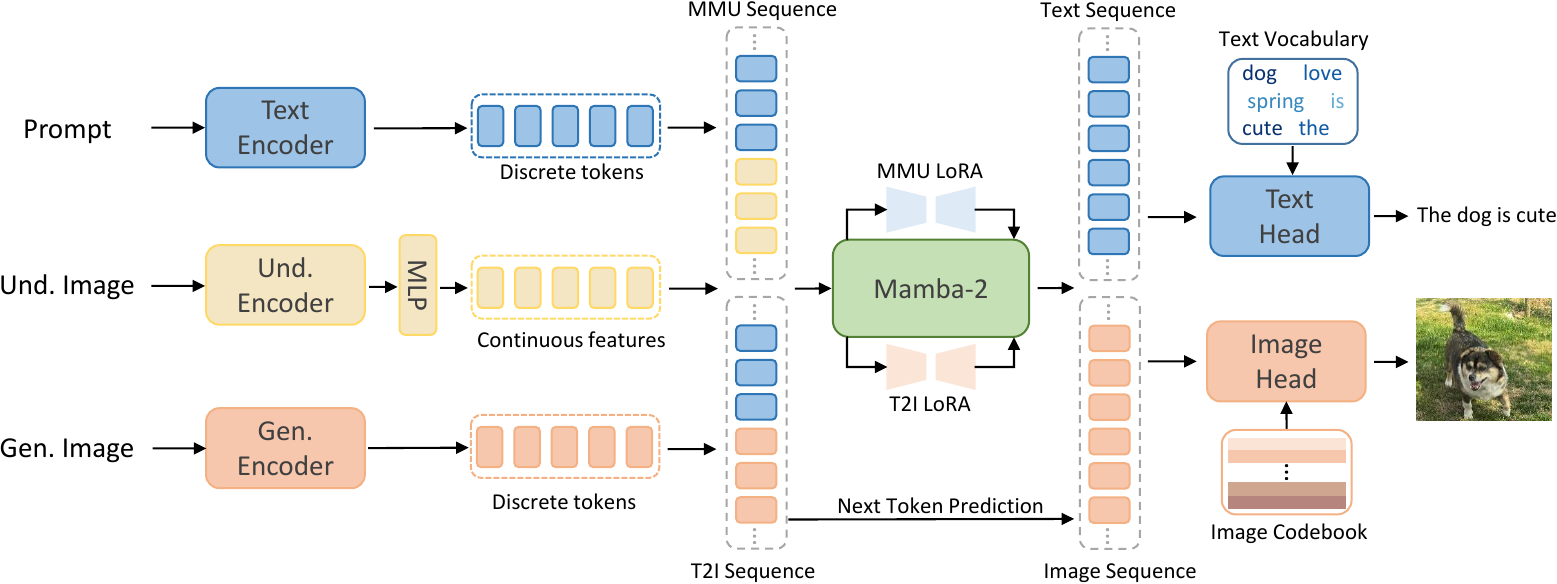 OmniMamba
 LightningDiT
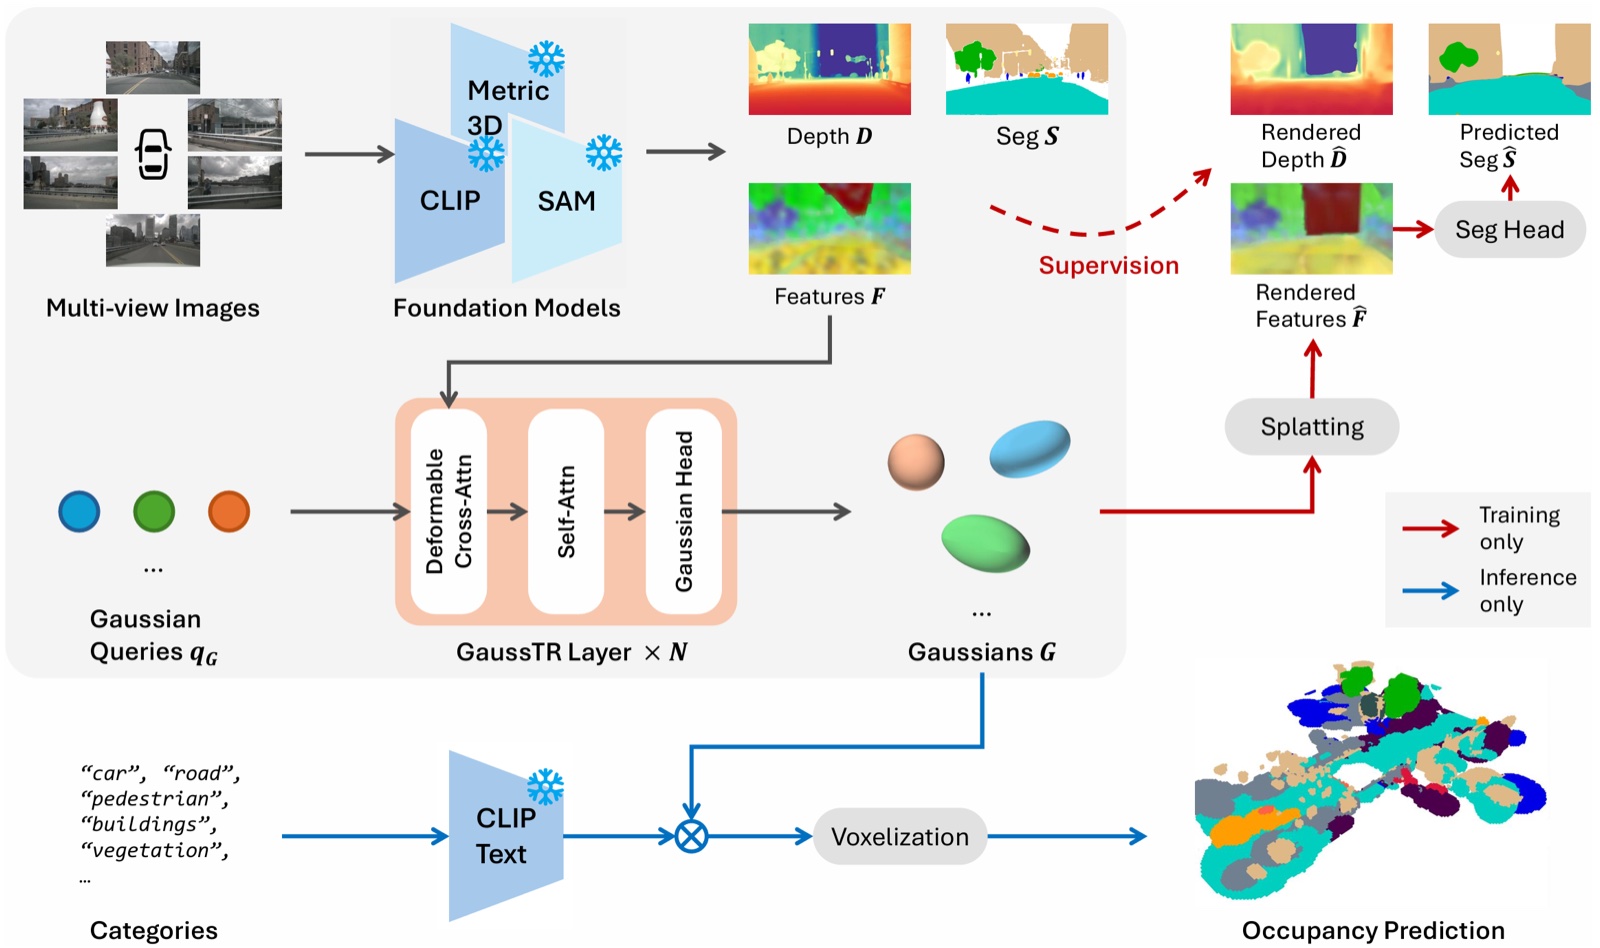 GaussTR
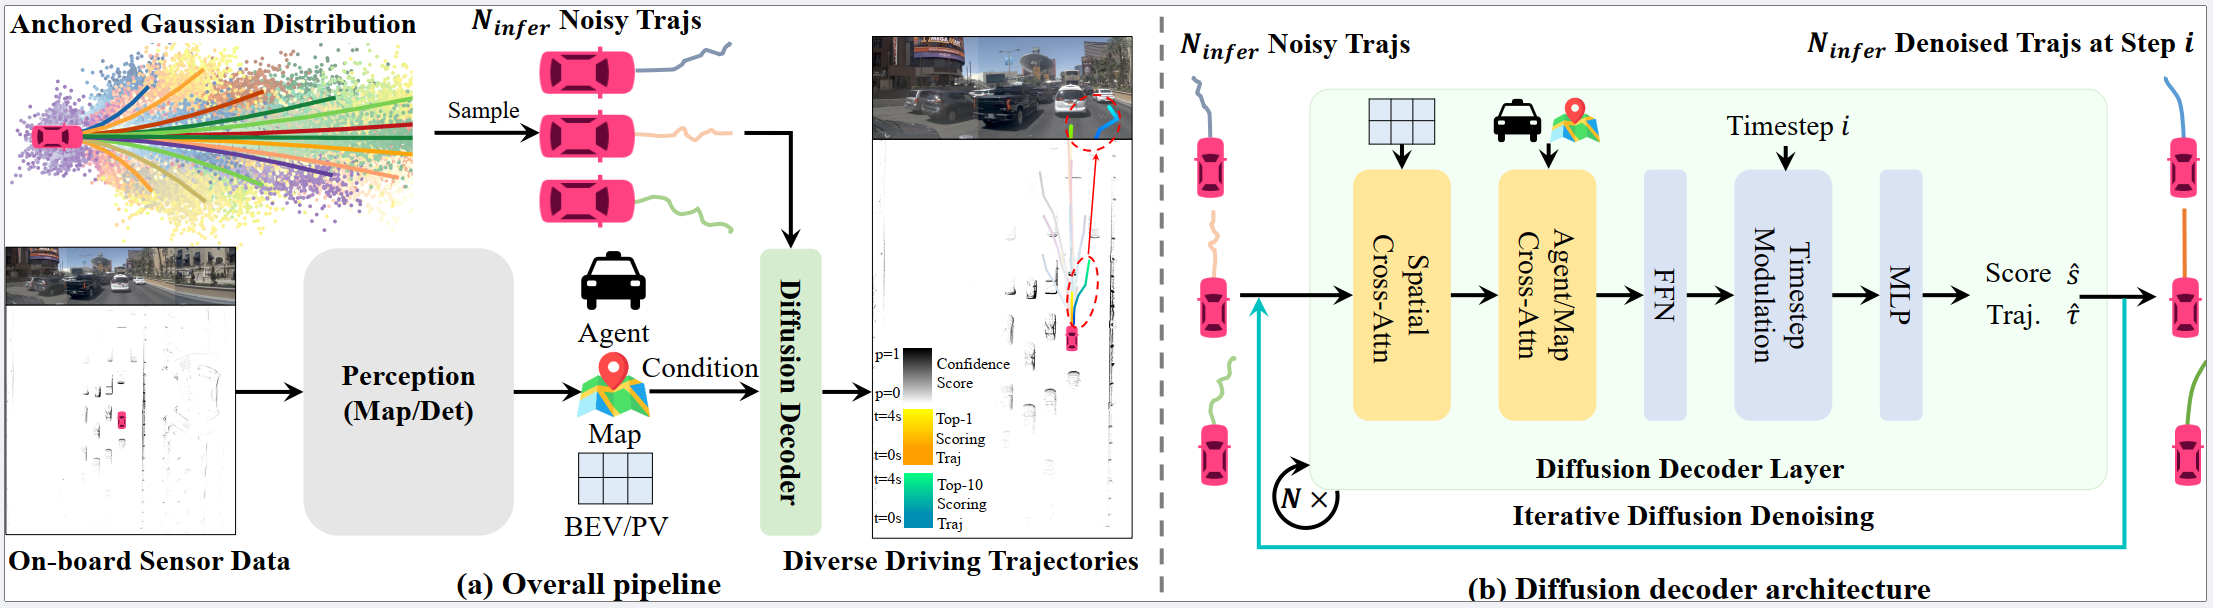 DiffusionDrive
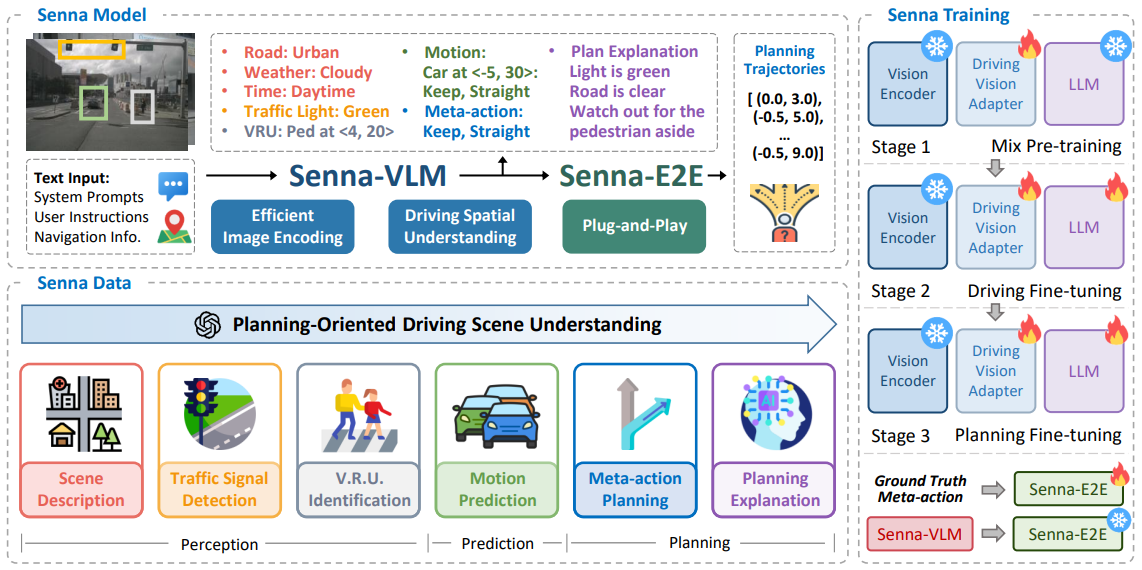 Senna
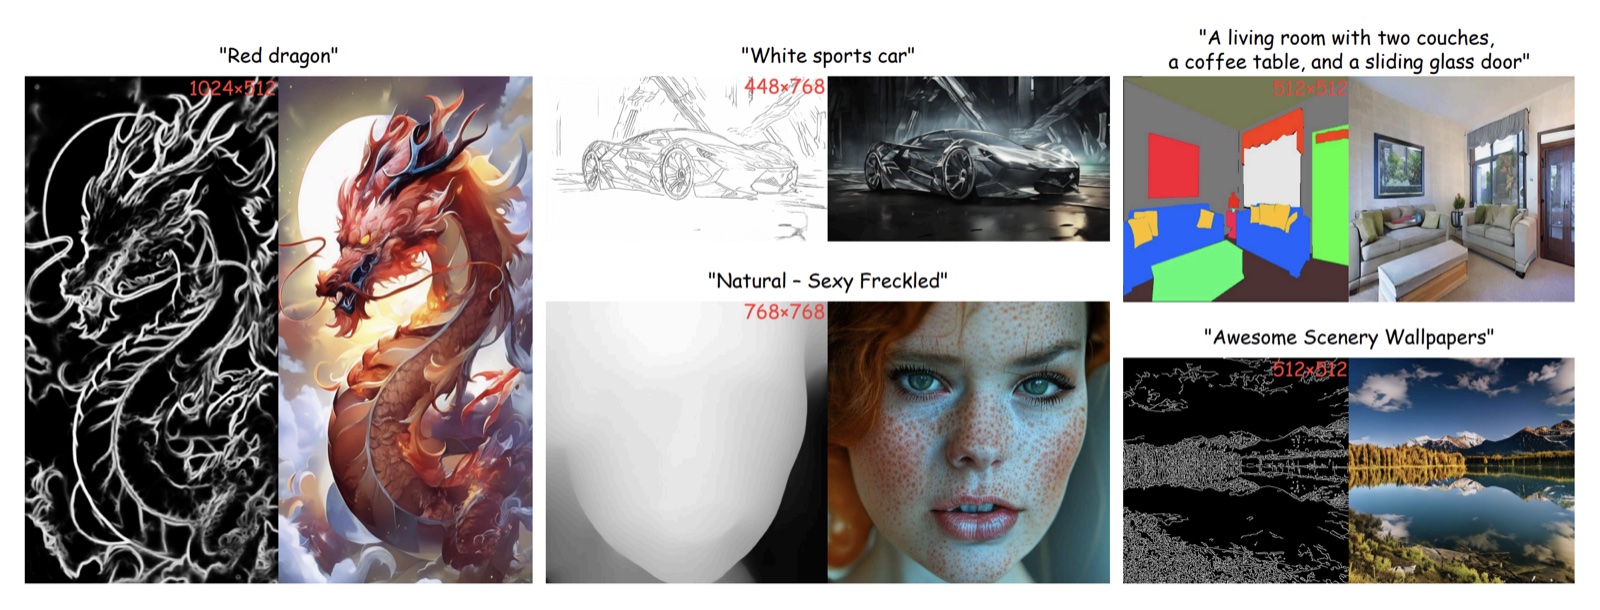 ControlAR
 DiG
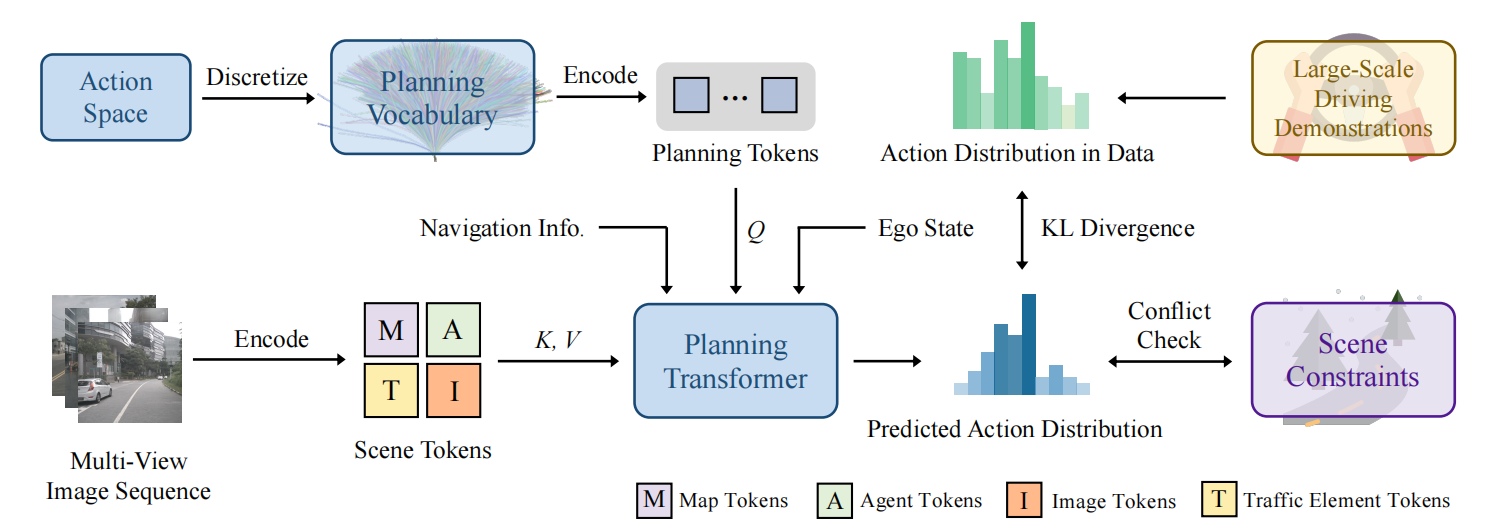 VADv2
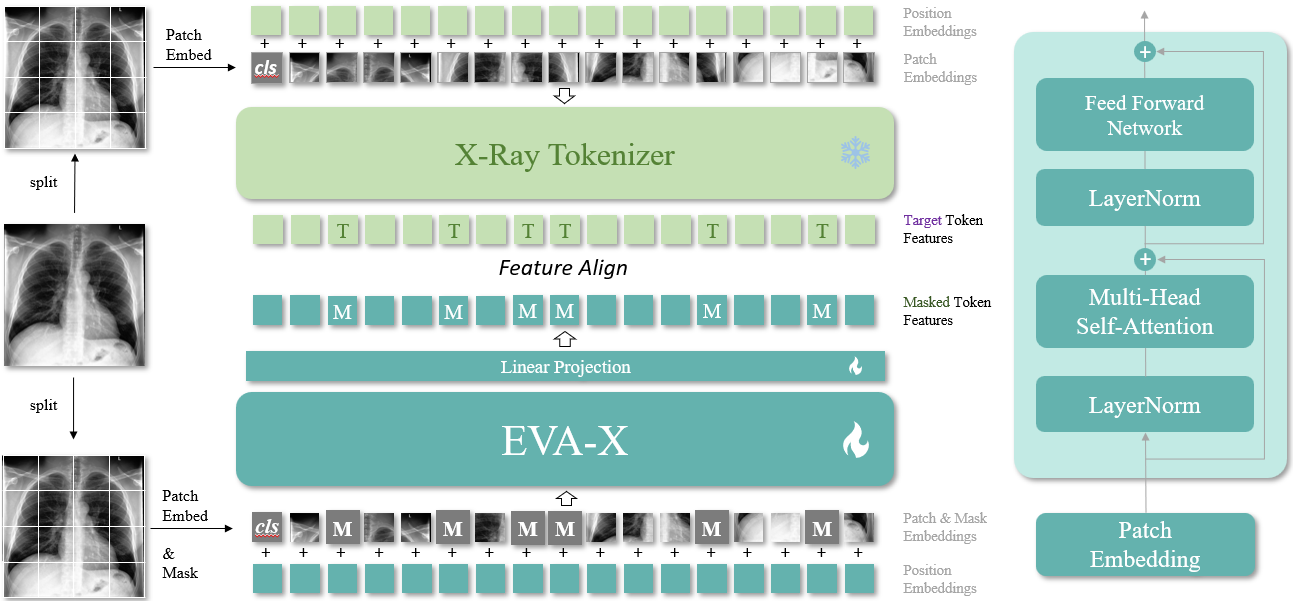 EVA-X
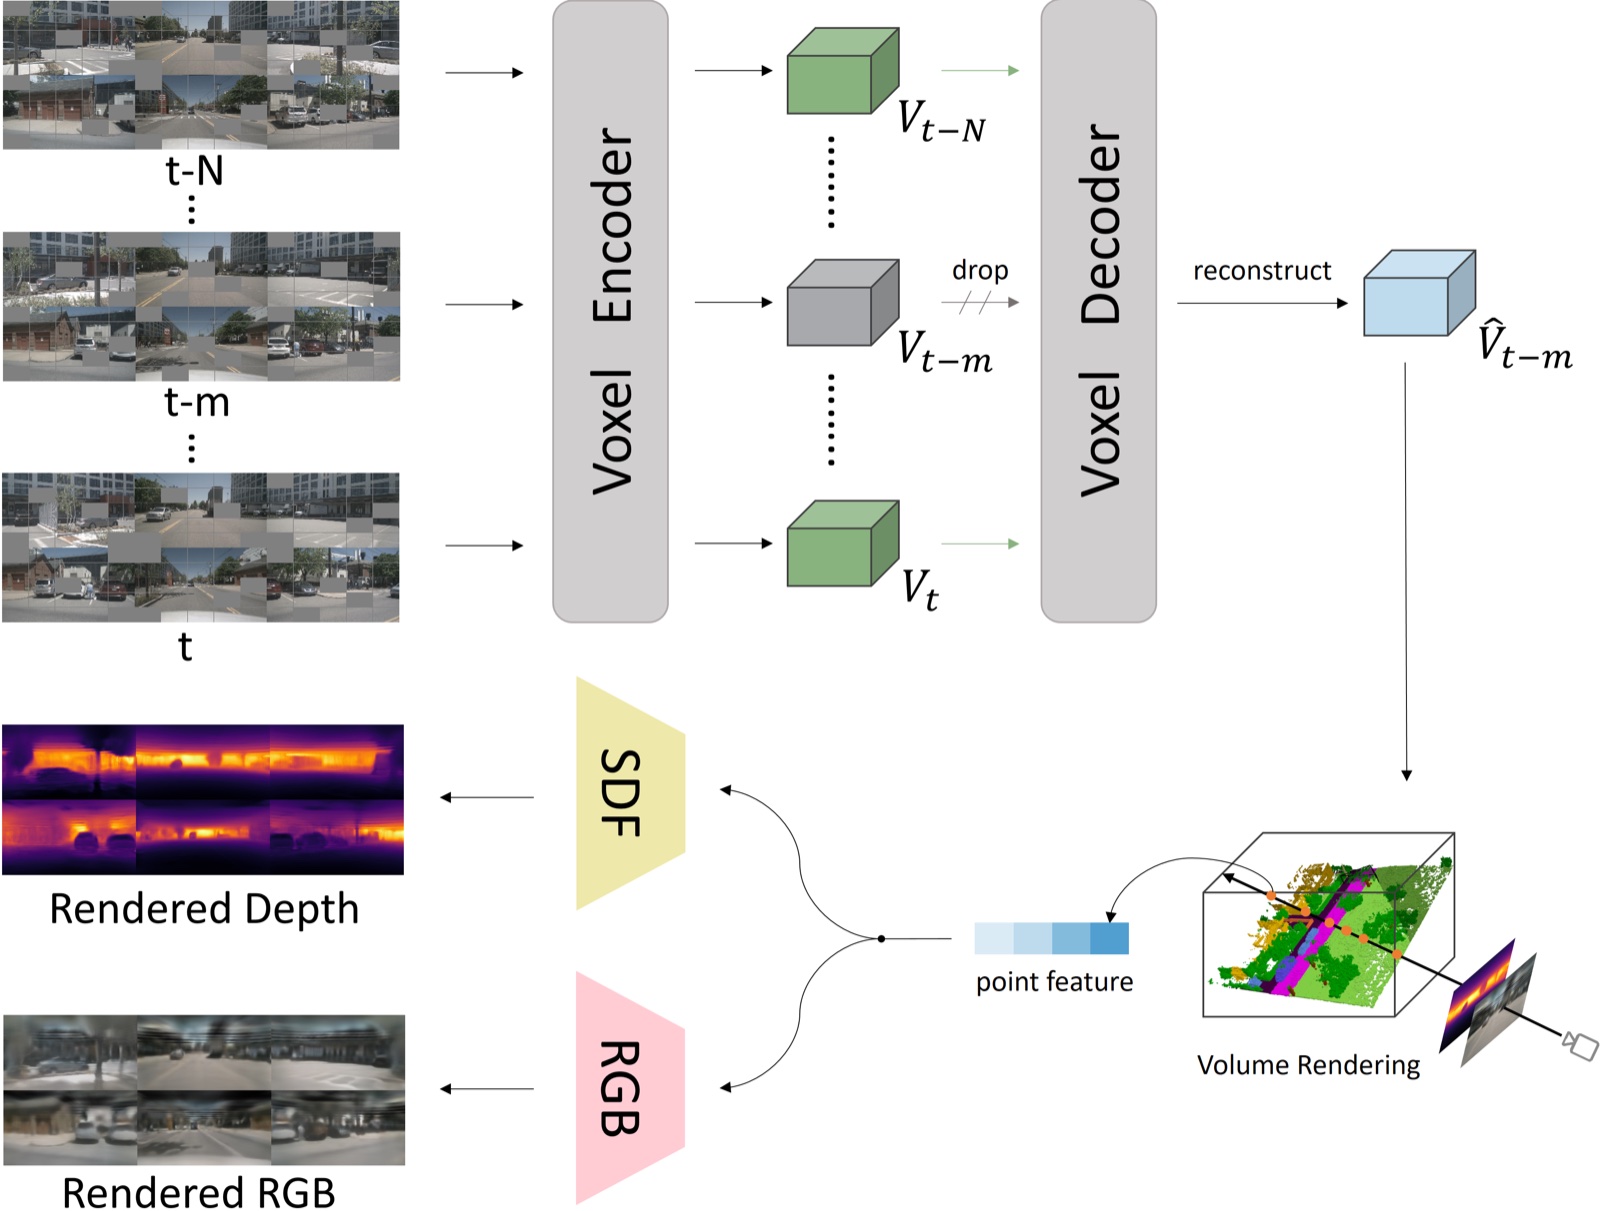 MIM4D
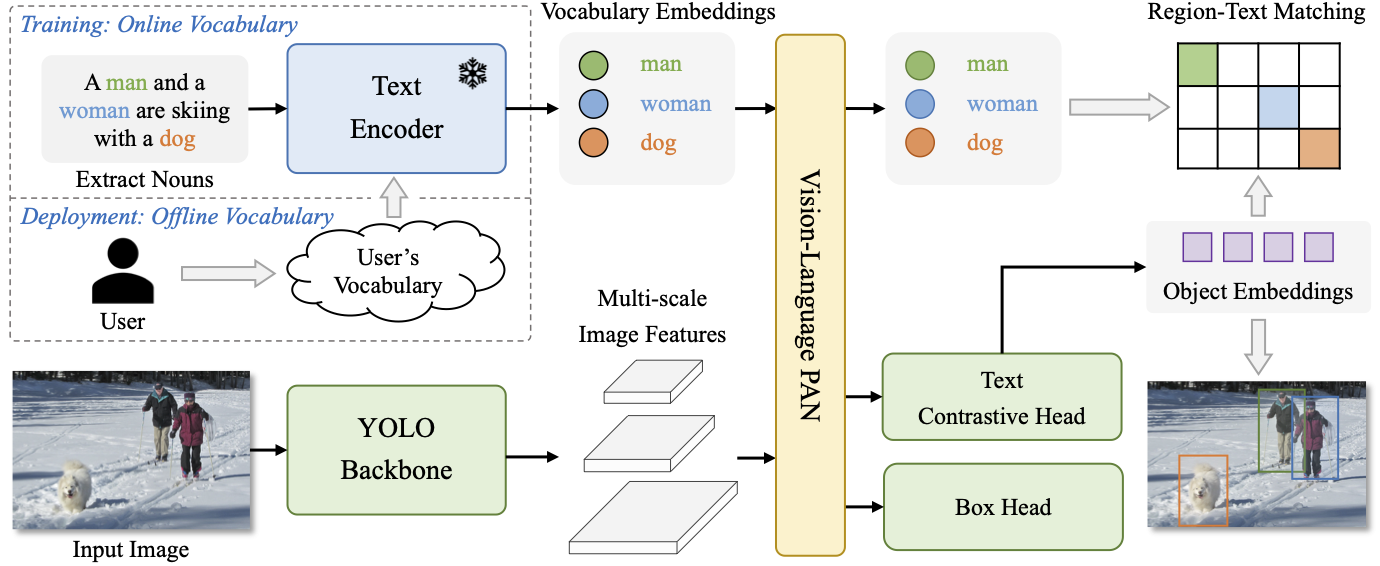 YOLO-World
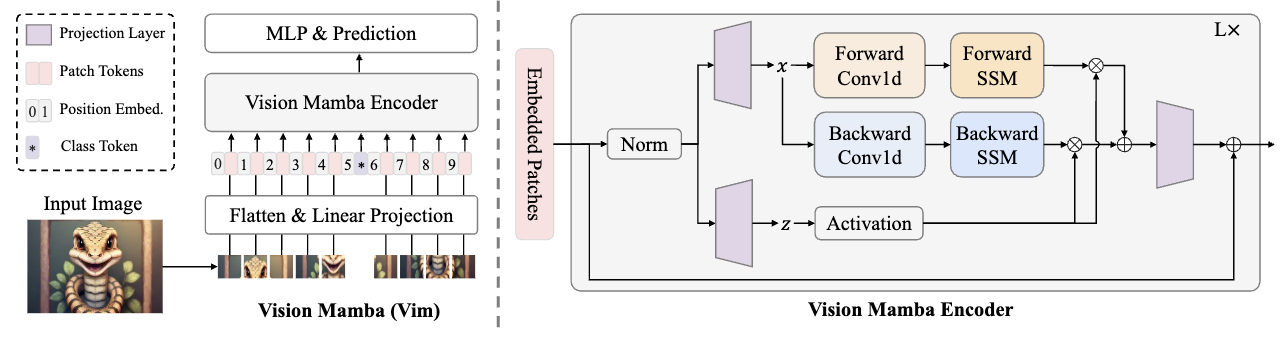 Vision Mamba
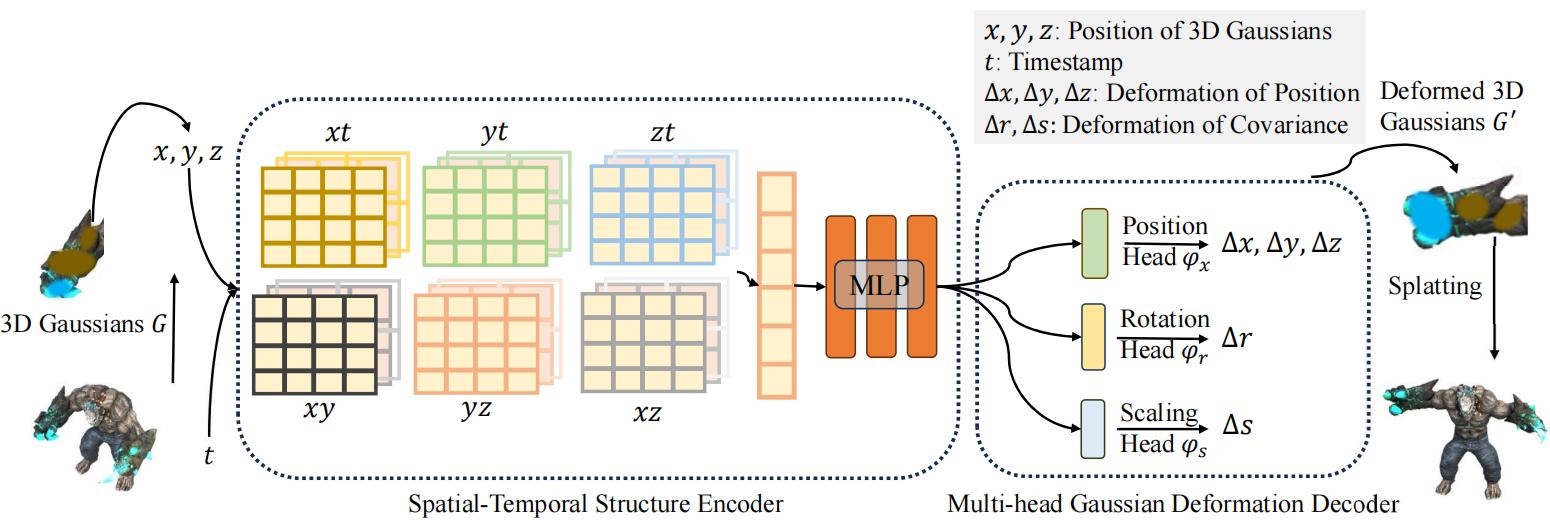 4DGaussians
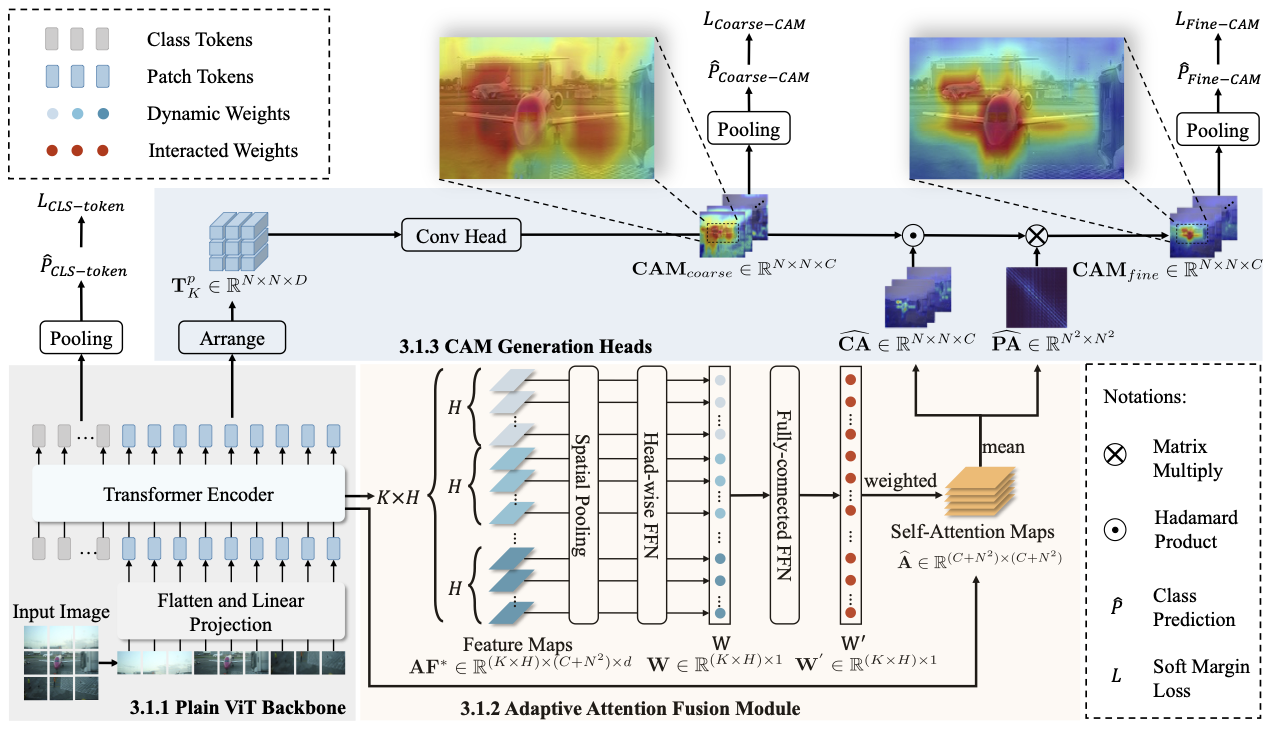 WeakTr
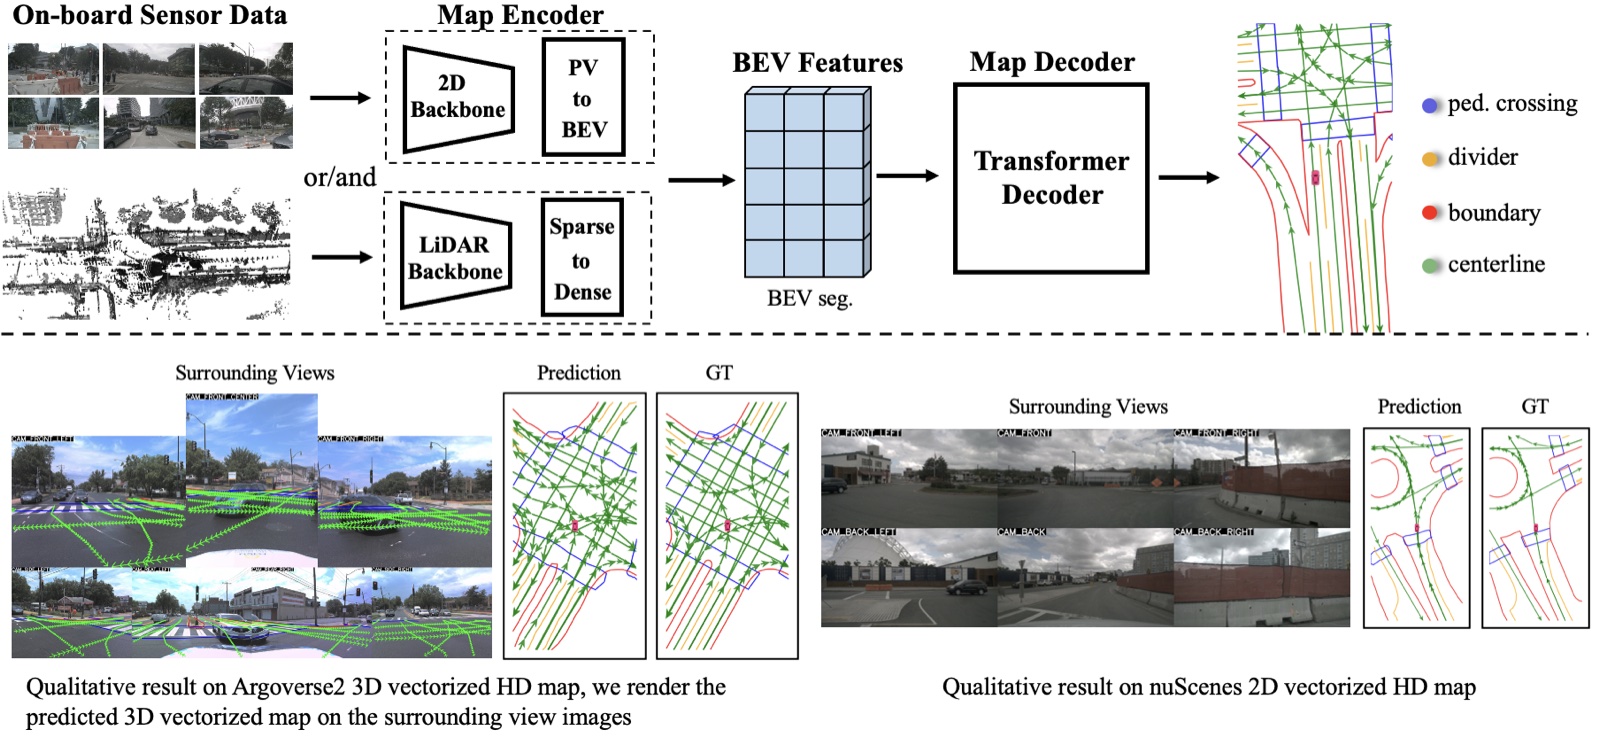 MapTR
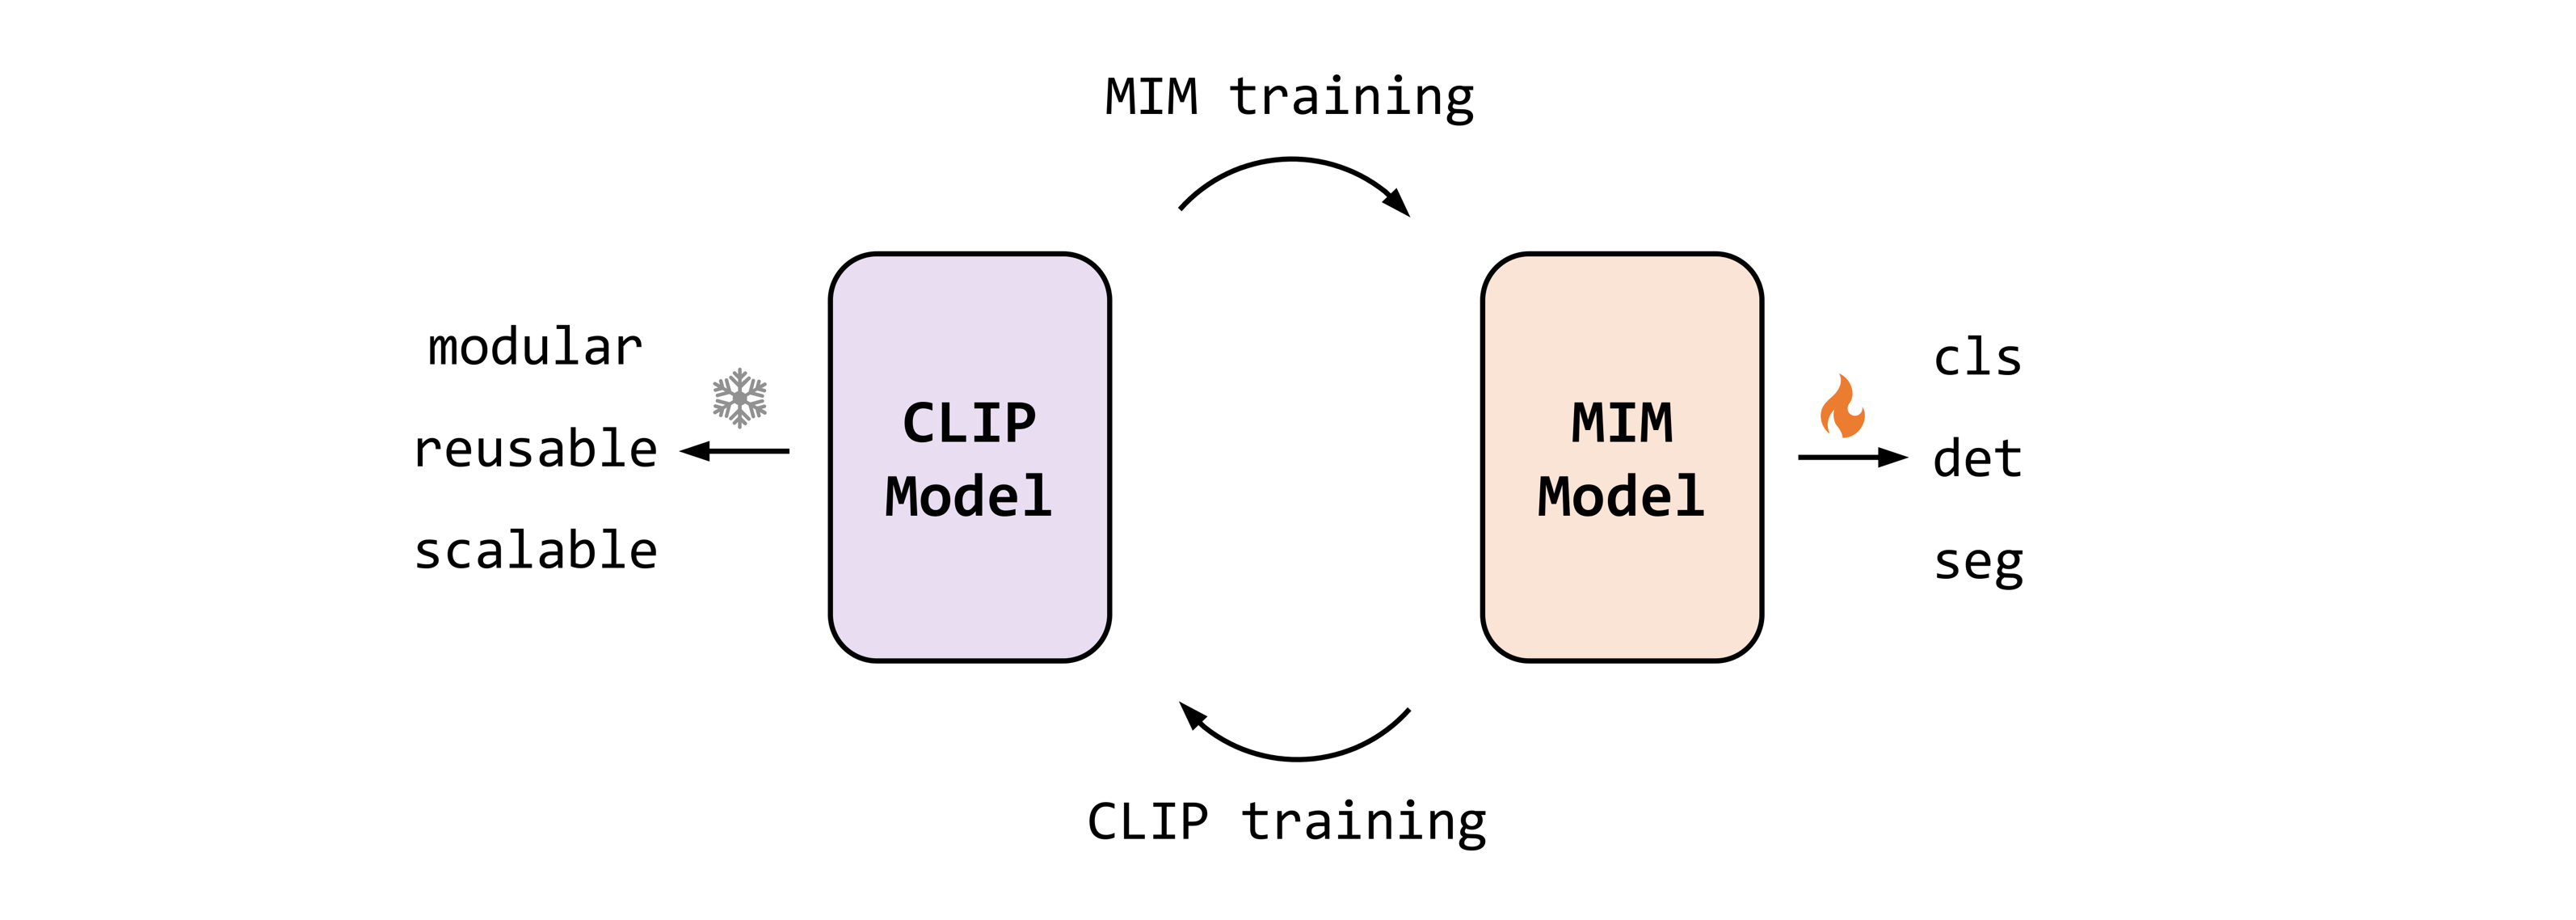 EVA
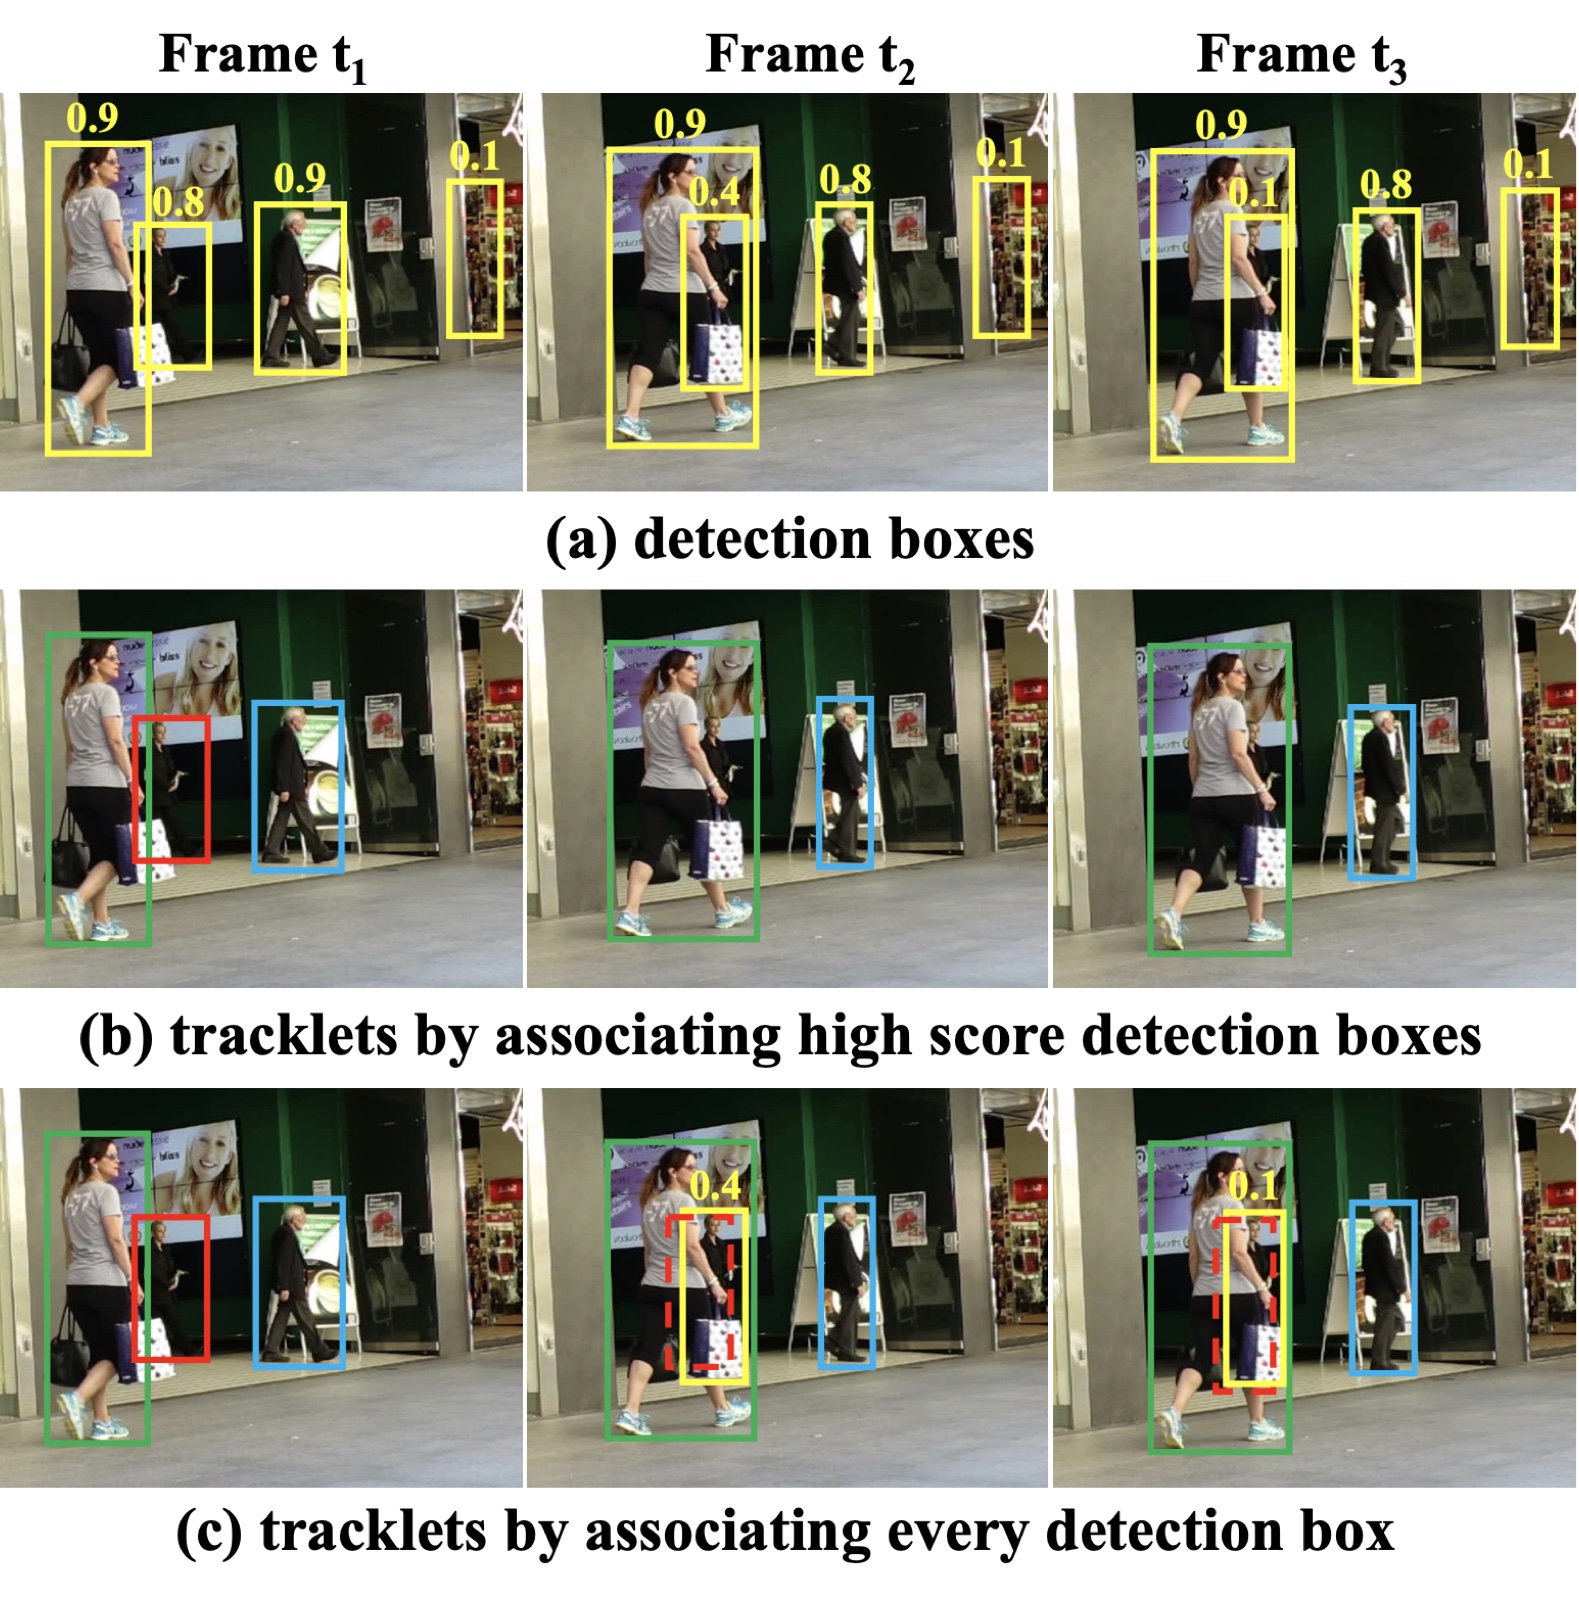 ByteTrack
 FairMOT
 CCNet
Some Highly Influential Papers
# first author is my student, * corresponding author
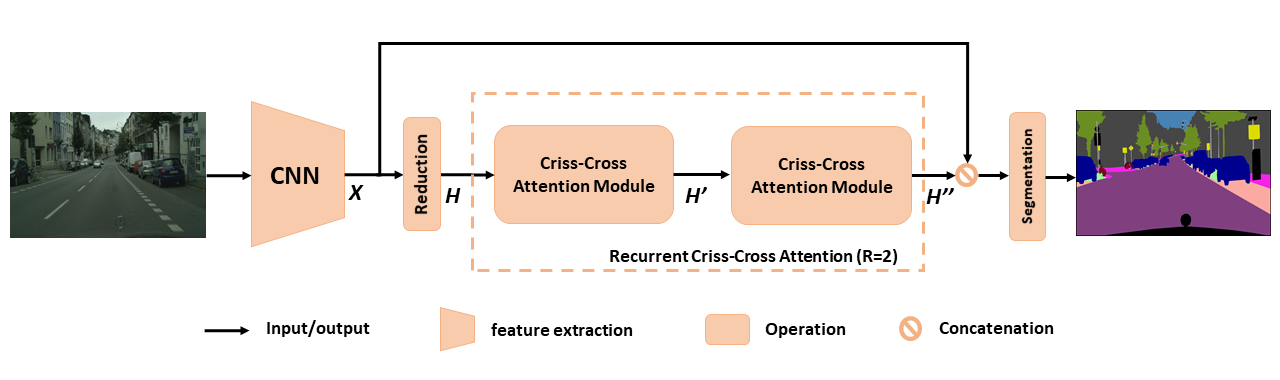
- Zilong Huang#, Xinggang Wang*, et al. CCNet: Criss-Cross Attention for Semantic Segmentation. ICCV 2019 & IEEE TPAMI 2023. 4,500+ citations, 1.5k stars, #5 most influential ICCV 2019, used in AlphaFold.
- Lianghui Zhu#, Bencheng Liao#, Qian Zhang, Xinlong Wang, Wenyu Liu, Xinggang Wang*. Vision Mamba: Efficient Visual Representation Learning with Bidirectional State Space Model. ICML 2024. 4,500+ citations, 3.9k stars.
- Yifu Zhang#, Peize Sun, Yi Jiang, Dongdong Yu, Fucheng Weng, Zehuan Yuan, Ping Luo, Wenyu Liu, Xinggang Wang*. ByteTrack: Multi-Object Tracking by Associating Every Detection Box. ECCV 2022. 4,400+ citations, 6.7k stars, #1 most influential ECCV 2022, integrated in YOLOv8.
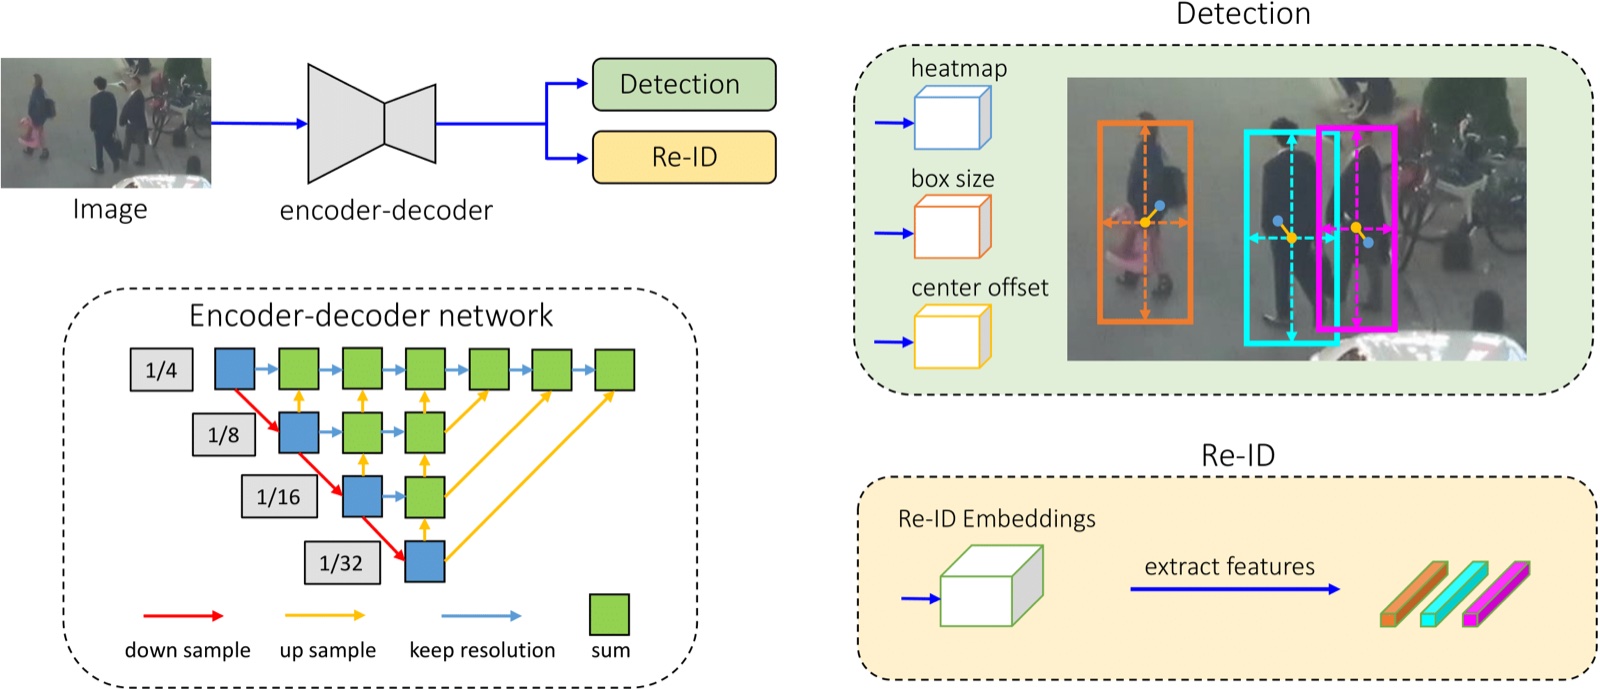
- Yifu Zhang#, Chunyu Wang, Xinggang Wang*, Wenjun Zeng, Wenyu Liu. FairMOT: On the Fairness of Detection and Re-Identification in MOT. IJCV 2021. 2,700+ citations, 4.2k stars.
- Guanjun Wu#, Taoran Yi#, Jiemin Fang, Lingxi Xie, Xiaopeng Zhang, Wei Wei, Wenyu Liu, Qi Tian, Xinggang Wang*. 4D Gaussian Splatting for Real-Time Dynamic Scene Rendering. CVPR 2024. 2,000+ citations, 4k stars, #3 most influential CVPR 2024.
- Zhaojin Huang#, Lichao Huang, Yongchao Gong, Chang Huang, Xinggang Wang*. Mask Scoring R-CNN. CVPR 2019 Oral. 1,500+ citations, 1.9k stars.
- Xinggang Wang, Xianbo Deng, Qing Fu, Qiang Zhou, Jiapei Feng, Hui Ma, Wenyu Liu, Chuansheng Zheng. COVID-19 Classification & Lesion Localization from Chest CT. IEEE TMI 2020. 1,400+ citations, 111 stars.
- Tianheng Cheng#, Lin Song*, Yixiao Ge, Wenyu Liu, Xinggang Wang*, Ying Shan. YOLO-World: Real-Time Open-Vocabulary Object Detection. CVPR 2024. 1,500+ citations, 6.6k stars.
- Yuxin Fang#, Wen Wang, Binhui Xie, Quan Sun, Ledell Wu, Xinggang Wang*, Tiejun Huang, Xinlong Wang*, Yue Cao*. EVA: Exploring the Limits of Masked Visual Representation Learning at Scale. CVPR 2023 Highlight. 1,300+ citations, 2.7k stars, #7 most influential CVPR 2023.
Media Coverage
"The Second Half of Foundation Model Architectures (大模型架构的下半场)", QbitAI
"Freeing Multimodal AI Models from "Memory Loss" (让多模态AI模型告别"记忆力衰退")", Sina Tech
"Venturing into Frontier Fields: He Made Computers "Sharp-Minded and Clear-Sighted" (勇闯前沿领域 他让计算机"脑聪目明")", Science and Technology Daily
"CVMJ Announces 2021 Best Paper Awards (CVMJ公布2021年度最佳论文奖)", Graphics & Geometry Computing
"New SOTA on Instance Segmentation: Mask Scoring R-CNN Tops Mask R-CNN on COCO", Medium
Academic Activities
Co-Editor in Chief: Image and Vision Computing
Area Chair: CVPR, ICCV, ECCV, NeurIPS, ICML, AAAI, ICIG, WACV, BMVC
Associate Editor/Editorial Board Member: IEEE TPAMI, Machine Vision and Applications, IEEE JBHI, Journal of Harbin Engineering University, Virtual Reality & Intelligent Hardware.
Reviewer for the following journals/institutes/conferences: National Natural Science Foundation of China (NSFC), European Research Council (ERC), Nature, Nature Computational Science, IEEE TPAMI, JMLR, Pattern Recognition, IEEE T. Cybernetics, IEEE TIP, IEEE TMM, IEEE TCSVT, IVC, IEEE TITS, CVIU, Neurocomputing, Scientific Reports, NeurIPS, ICDM, ICCV, ECCV, CVPR, ICME, ICIP, ICPR, AISTATS, ICML, ICLR.
Website chair of VALSE 2016 / Website chair of IEEE SIDAS 2016 / Website chair of IEEE CAS conference on intelligent media computing
Committee member of CSIG Image & Video Communication Committee and CSIG Machine Vision Committee, Executive committee member of CCF Computer Vision Committee, VALSE Online Committee member (1st-3rd terms), VALSE Senior AC, Member of CSIG, Member of CCF, Senior Member of IEEE
Awards
Clarivate "Highly Cited Researcher", 2025
Elsevier "Highly Cited Chinese Researcher", 2021 - present
Young Top-notch Talent of the National "Ten Thousand Talents Program", 2021
Hubei Youth May 4th Medal, 2023
CSIG Young Scientist Award, 2022
Wu Wenjun AI Excellent Young Scholar Award, 2021
Second Prize of Hubei Provincial Natural Science Award (ranked 1st), 2025
Young Talent Support Program of China Association for Science and Technology, 2015
Microsoft Research Asia Fellowship, 2012 (10 recipients in Asia-Pacific) [more information]
Excellent Award of CCF-Tencent Research Fund, 2017
Research Funding
NSFC Joint Fund Key Project (U25B2067), Self-Learning Mechanisms for Multimodal State-Space Foundation Models in Open Environments, 2026.01 - 2029.12
National Key R&D Program of China (2022YFB4500602), Natural Human-Computer Interaction with Multi-Channel Fusion, 2022.10 - 2025.09
NSFC 62276108, Large-Scale Weakly-Supervised Object Detection and Segmentation in Open Scenes, 2022.01 - 2026.12
NSFC 61876212, Weakly-Supervised Image Understanding via Visual Relationship Learning, 2019.01 - 2022.12
Major Project of Hubei Provincial Technology Innovation Program, 2017.07 - 2019.12
HUST-Horizon Robotics Joint Research Center for Computer Vision, 2017 - 2020
CCF-Tencent Rhino-Bird Research Fund, 2017
NSFC 61503145, Image Representation Based on Discriminative Codebooks, 2016.01 - 2018.12
Young Elite Scientists Sponsorship Program by CAST (No. YESS 20150077), 2015 - 2017
Short Bio
He completed his Ph.D. and B.E. in Huazhong University of Science and Technology in 2014 and 2009 respectively. His Ph.D. supervisors were Prof. Wenyu Liu and Prof. Xiang Bai. During his Ph.D. period, he visited UCLA and Temple University where he was supervised by Prof. Alan Yuille and Prof. Longin Latecki, respectively. He also worked in the visual computing group in Microsoft Research Asia as an intern, supervised by Prof. Zhuowen Tu and collaborated with Prof. Yi Ma.